Find files, editable templates and browser test targets by what you need to make or test. The directory below is cut by format; the two collections under it cut the same library by subject and by workflow.
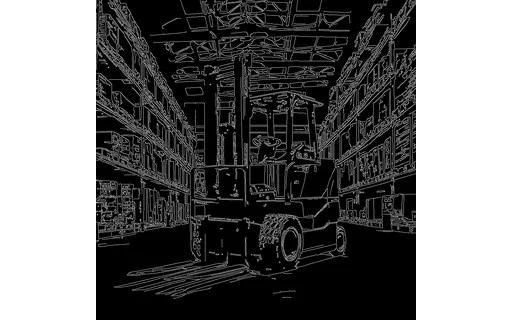
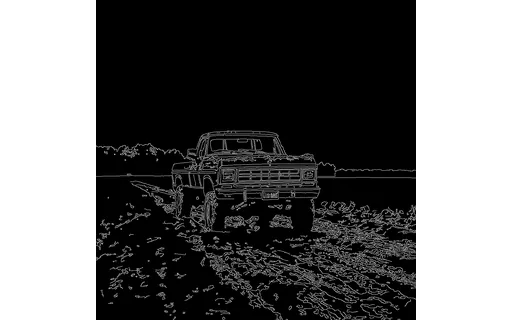
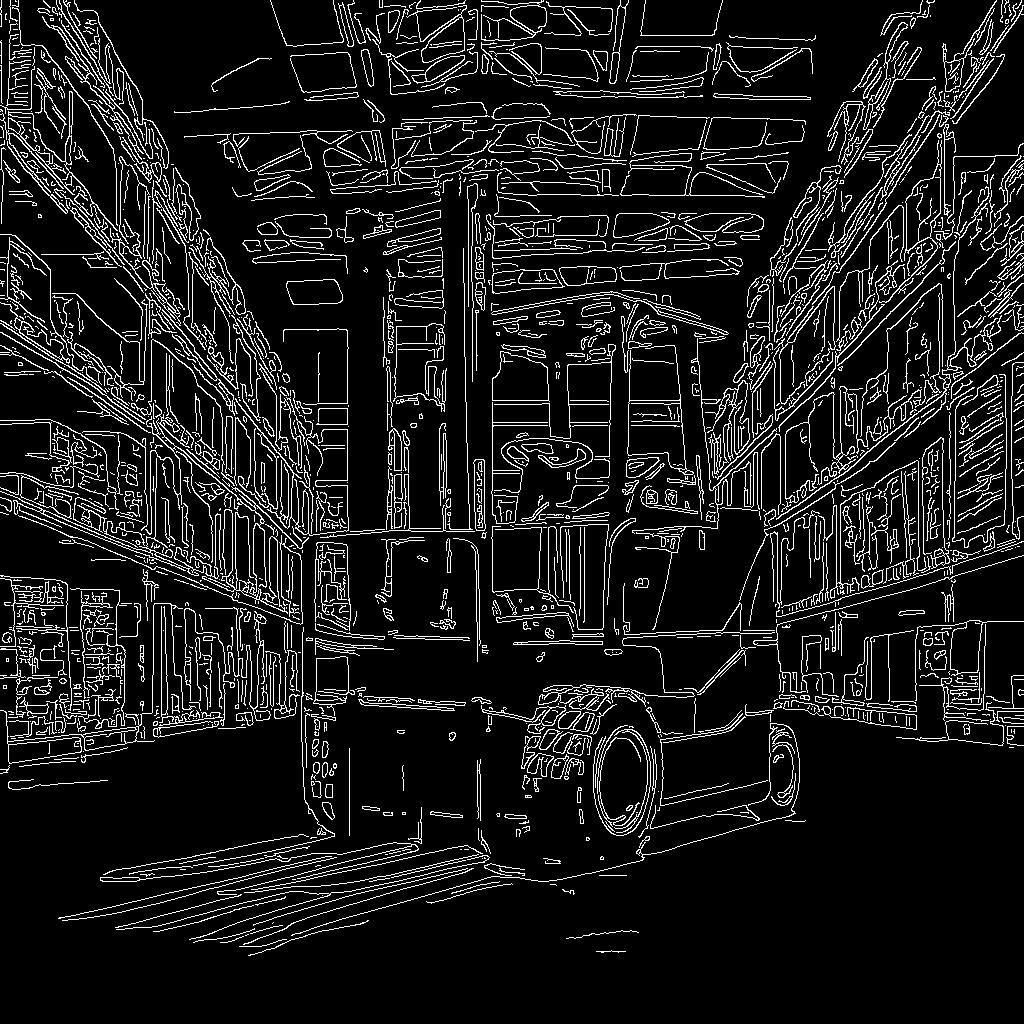
A canny edge map for the published plate v-forklift.png, 1024x1024. Canny edge detection at low threshold 0.1 and high 0.3, run at the plate's own resolution so the edges land on the same pixels as the photograph they came from. Lit coverage measures 10.0% of the frame. The plate and this map are the same scene at the same size, so they can be compared pixel for pixel rather than by eye.
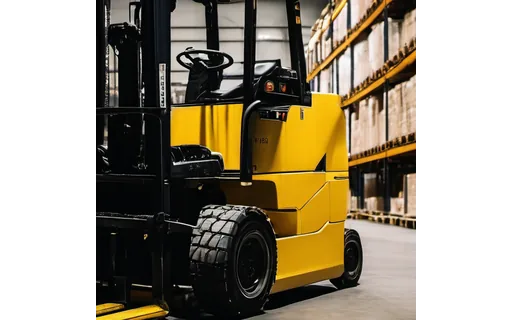
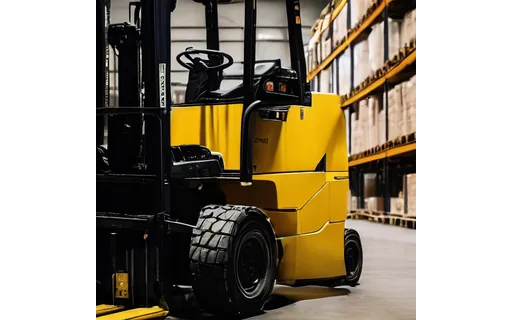
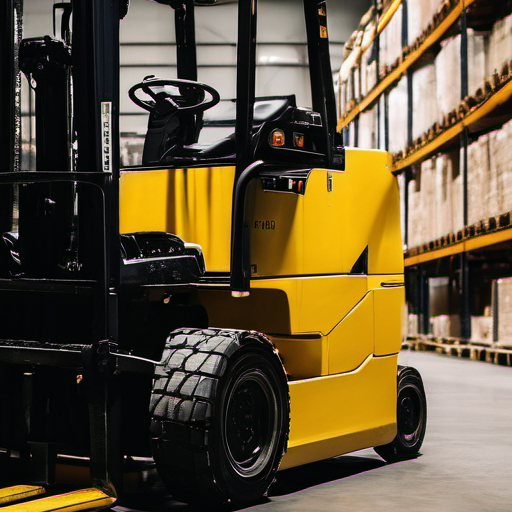
A clean 512x512 crop of yellow forklift in a warehouse aisle, industrial lighting, taken from the published plate v-forklift.png before anything was added to it. This is the ANSWER KEY for its group: the object in the source file was composited onto this image, so this is exactly what was behind it. Nothing else in the group came from a second tool's guess.
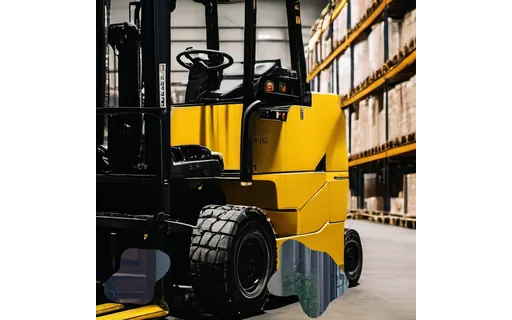
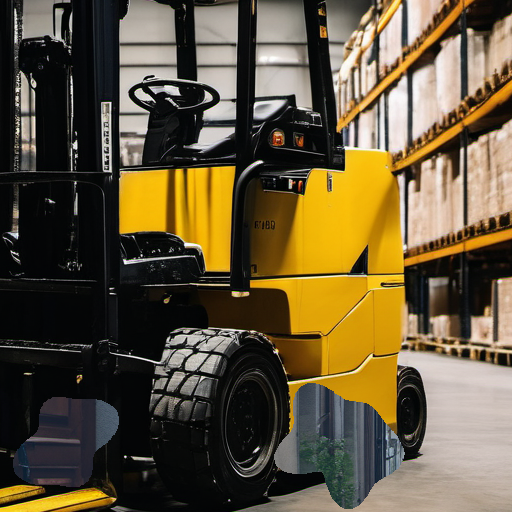
The same view of yellow forklift in a warehouse aisle, industrial lighting, with a foreign object composited over 6.26% of the frame as two disconnected regions - the case a reader that keeps only the largest connected component, or takes the bounding box of both, gets wrong. This is the file an object-removal tool is given. Outside the mask it is byte-identical to the clean plate beside it, so any difference a tool leaves there is damage it did rather than content it was handed.
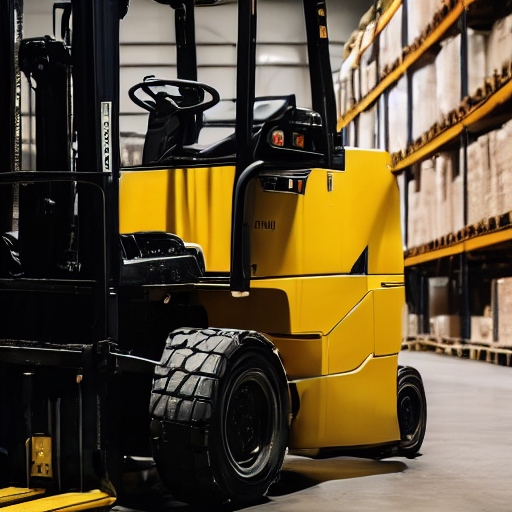
Yellow forklift in a warehouse aisle, industrial lighting, with the object taken back out by Stable Diffusion 1.5 inpainting and the gap reconstructed from the surrounding context alone - the masked latents are erased before sampling, so the model never saw what it was painting over. Inside the mask it differs from the source by 54.408/255 and from the ground-truth plate by 33.846/255; the second number is NOT expected to be small, because an inpainter invents plausible content rather than recovering what was there. Beyond a 16-pixel ring around the mask the frame changes by only 7.135/255, which is the full-frame VAE round trip and not an edit.
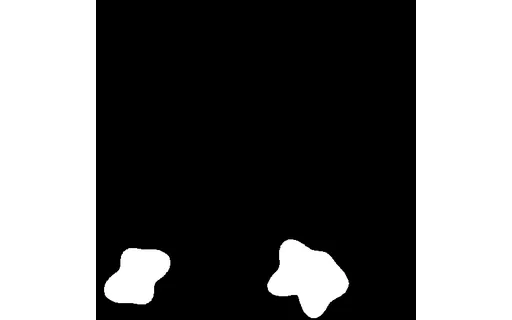
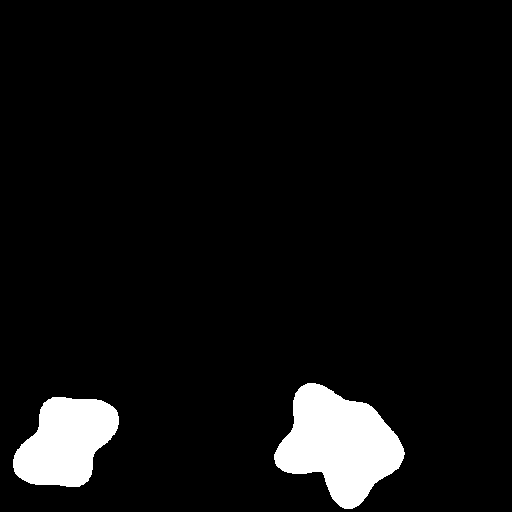
The exact footprint of the object sitting over yellow forklift in a warehouse aisle, industrial lighting, as an 8-bit mask covering 6.26% of the frame as two disconnected regions - the case a reader that keeps only the largest connected component, or takes the bounding box of both, gets wrong. It holds only the values 0 and 255. The footprint is what DREW the object, so it is ground truth by construction rather than a segmentation of it. Hard-edged on purpose: a feathered edge has no exact footprint, and the exactness is the point of shipping it.
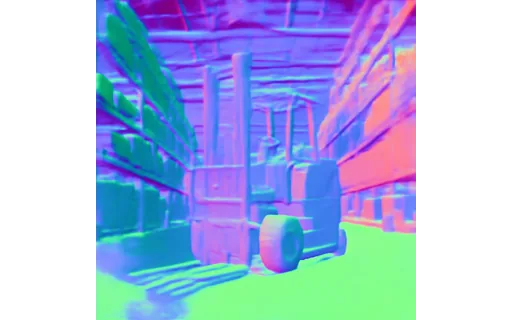
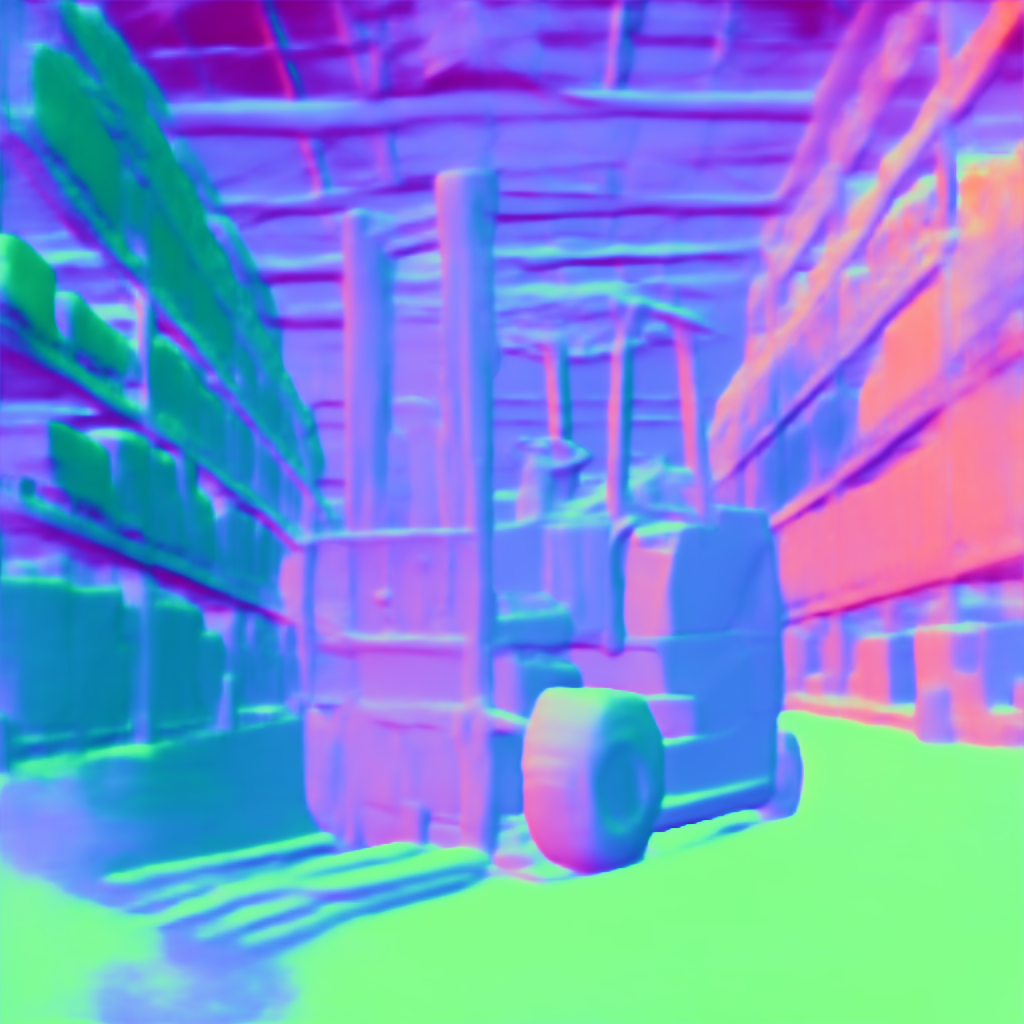
A tangent-space surface normal map for the published plate v-forklift.png, 1024x1024 - the same size as the plate, so the two compare pixel for pixel with no resample in between. RGB encodes the XYZ surface direction remapped from -1..1 into 0..255. Decoded back to vectors this file measures a mean length of 0.9973, which is the number to check your own decode against: a reader that transposes the channels or inverts the remap still produces a plausible-looking image, and lights the surface the wrong way.
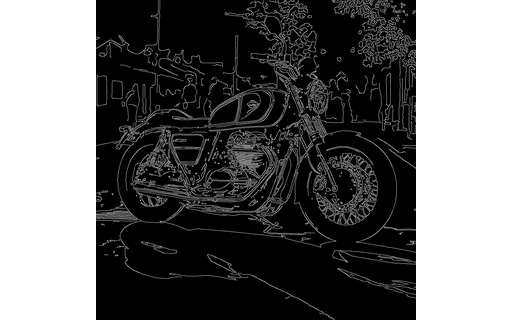
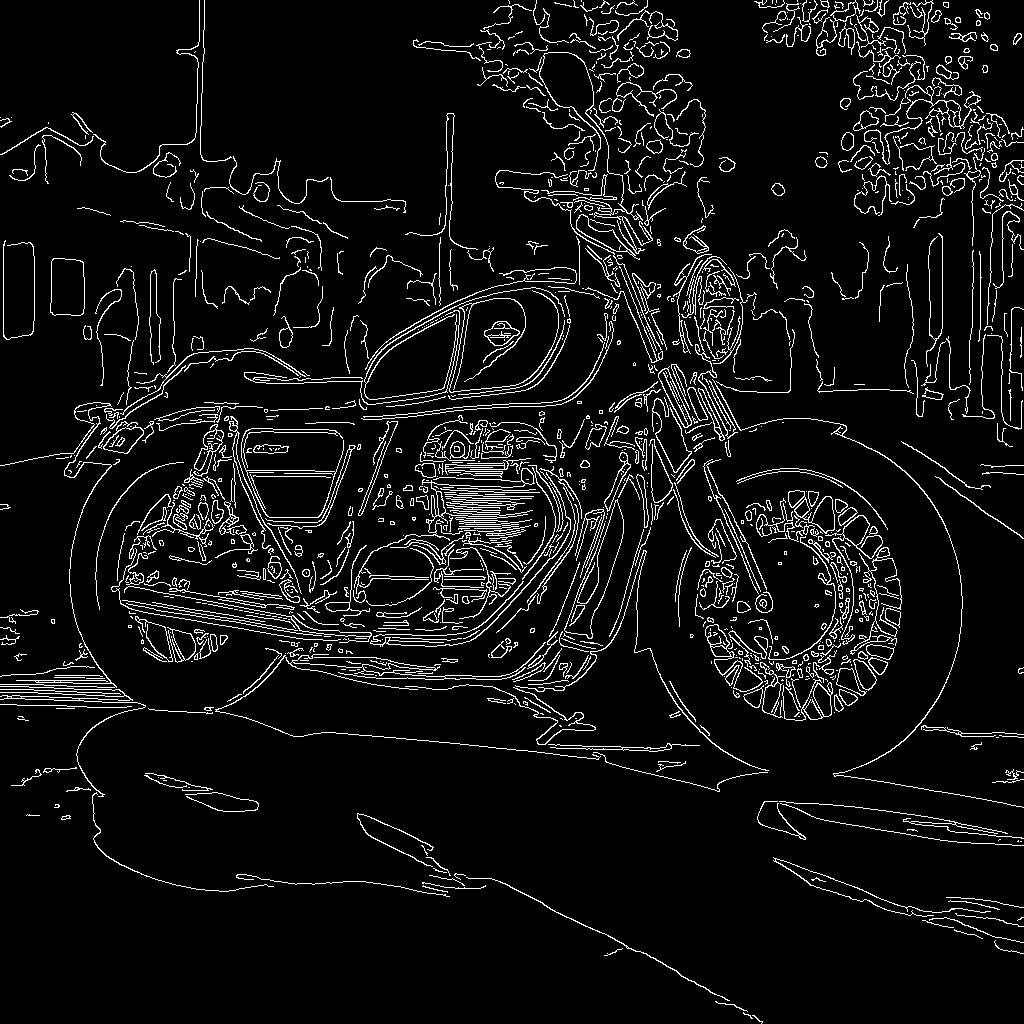
A canny edge map for the published plate v-moto-sport.png, 1024x1024. Canny edge detection at low threshold 0.1 and high 0.3, run at the plate's own resolution so the edges land on the same pixels as the photograph they came from. Lit coverage measures 6.6% of the frame. The plate and this map are the same scene at the same size, so they can be compared pixel for pixel rather than by eye.
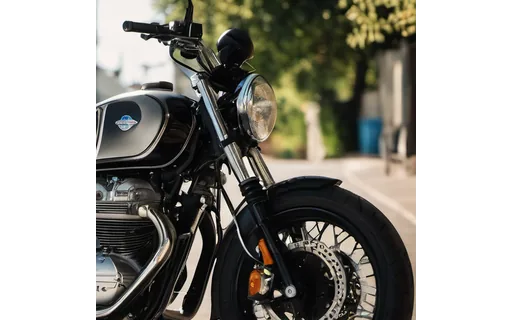
The same view of sports motorcycle parked at a kerb, sunny day, expanded to 768x512 - 128 pixels added to the left and right, the symmetric case - so 33.3% of this frame is invented canvas. The original sits at pixels 128,0 to 640,512. Compare it INSET by 40 pixels: over that core it differs from the original by only 8.192/255, the VAE round trip, but over the whole rectangle by 10.954/255, because the pad deliberately feathers the original's outer edge into the new area. A test that expects the whole rectangle untouched fails on a correct tool.
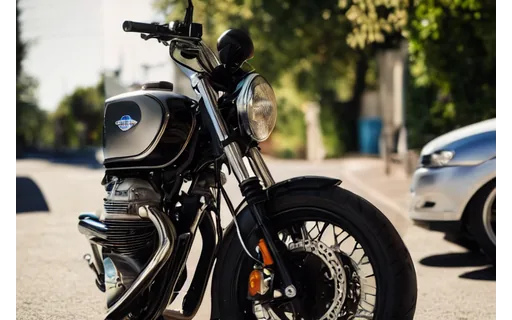
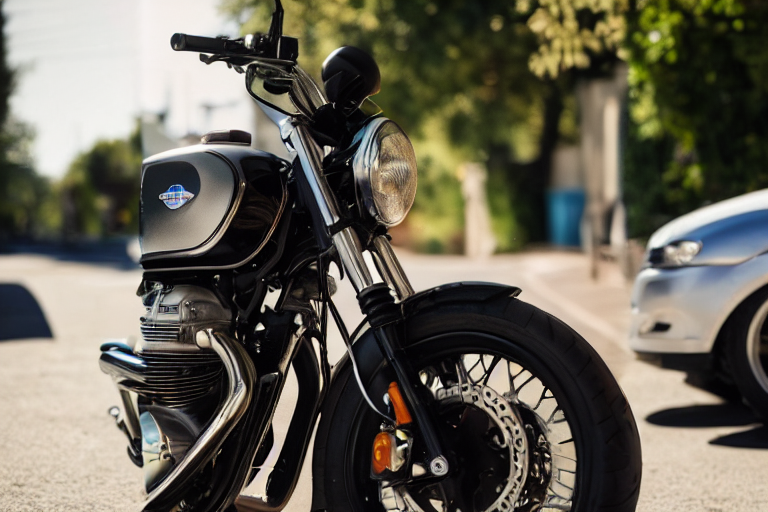
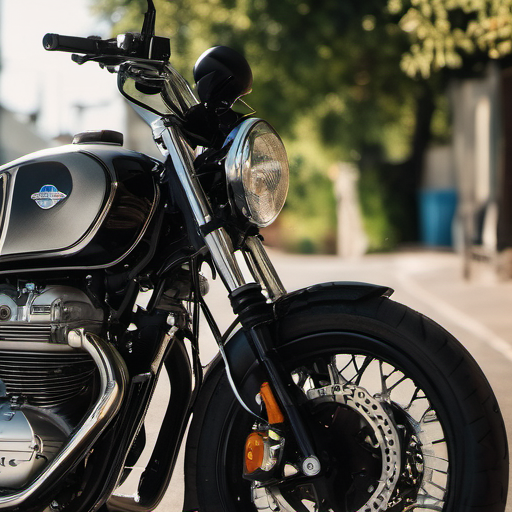
A 512x512 view of sports motorcycle parked at a kerb, sunny day - the frame an outpainting tool is given, cropped from the published plate nss-v-moto-sport_00001_.png. Its companion expands it to 768x512 with 128 pixels added to the left and right, the symmetric case, and the boundary record in this group states the exact rectangle this image occupies inside that frame - so where it ended up can be checked rather than eyeballed.
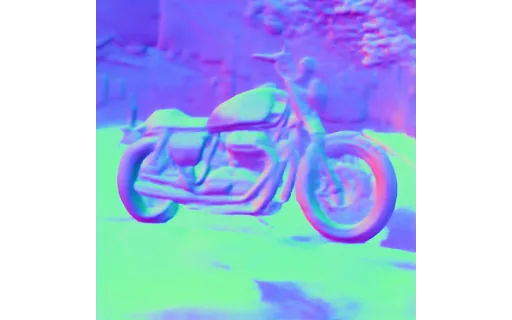
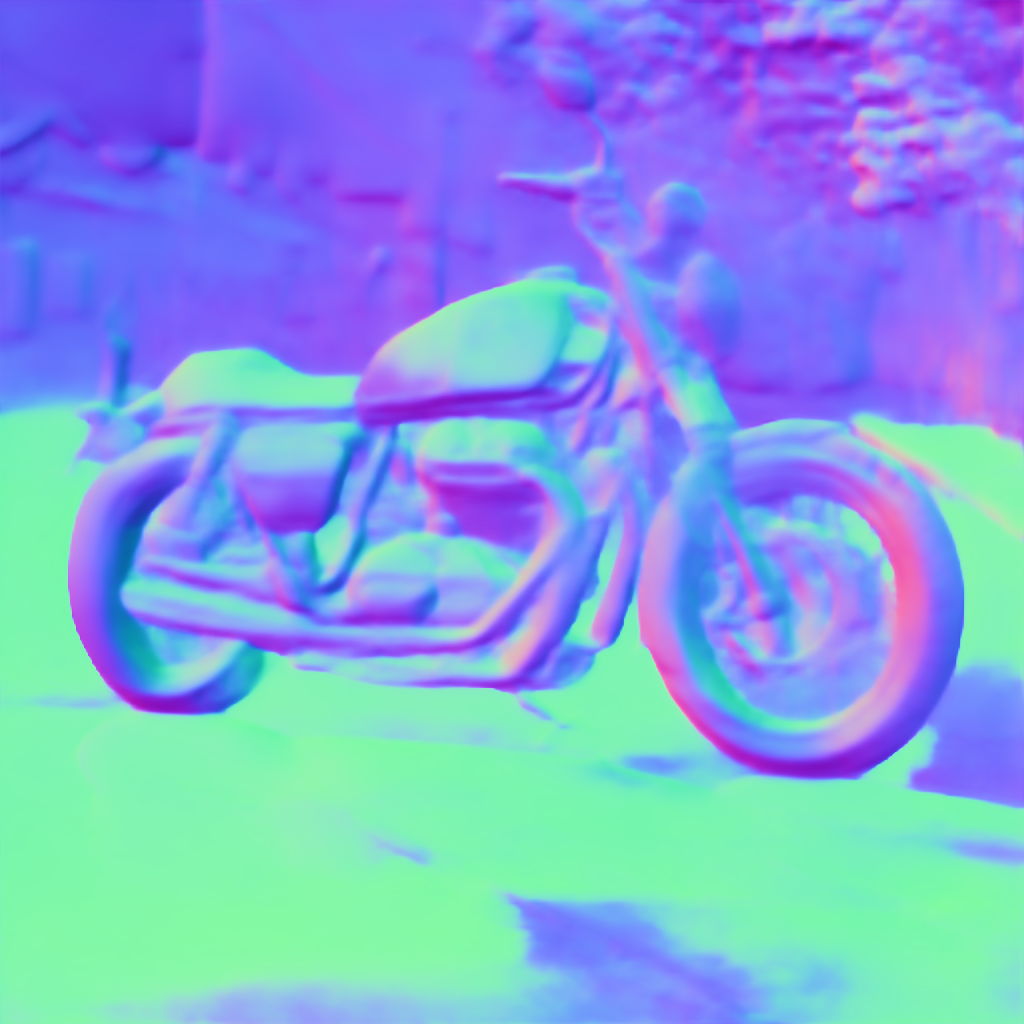
A tangent-space surface normal map for the published plate v-moto-sport.png, 1024x1024 - the same size as the plate, so the two compare pixel for pixel with no resample in between. RGB encodes the XYZ surface direction remapped from -1..1 into 0..255. Decoded back to vectors this file measures a mean length of 0.996, which is the number to check your own decode against: a reader that transposes the channels or inverts the remap still produces a plausible-looking image, and lights the surface the wrong way.
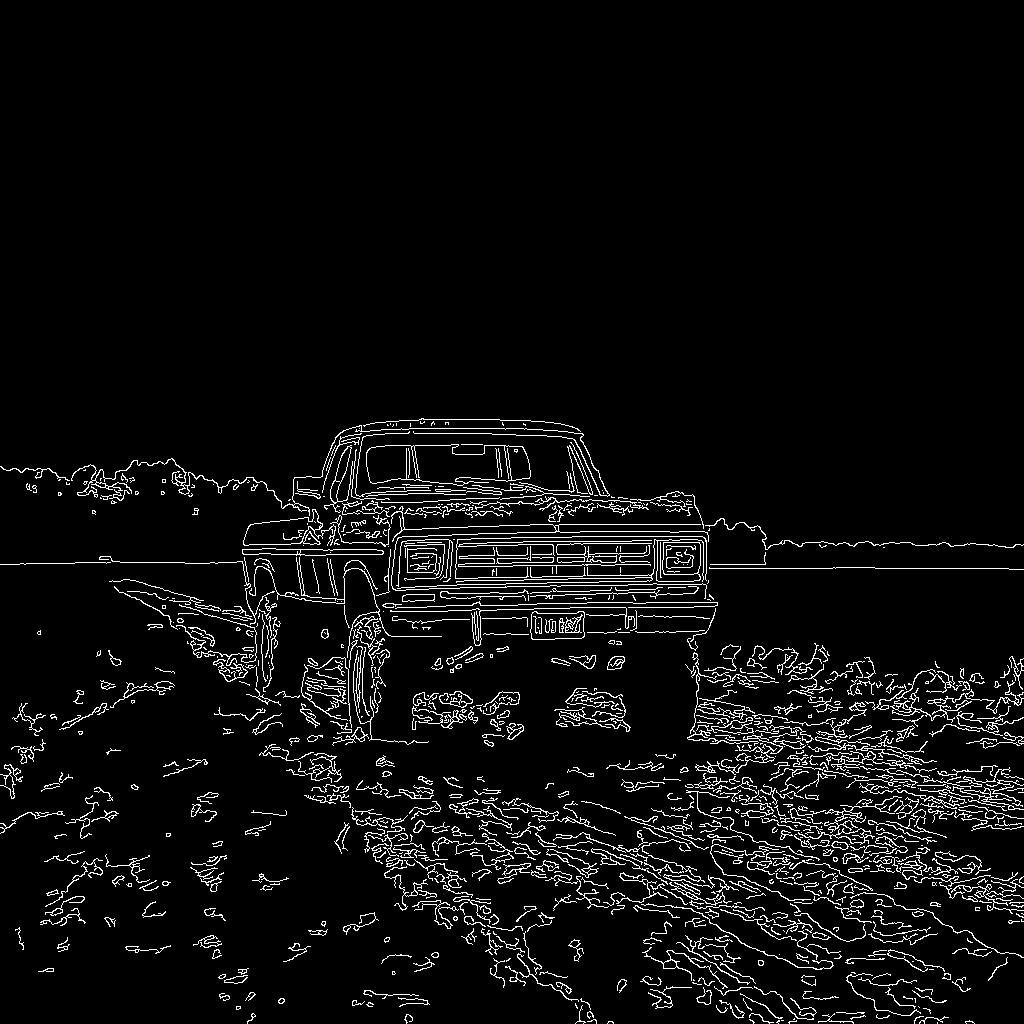
A canny edge map for the published plate v-pickup-mud.png, 1024x1024. Canny edge detection at low threshold 0.1 and high 0.3, run at the plate's own resolution so the edges land on the same pixels as the photograph they came from. Lit coverage measures 5.1% of the frame. The plate and this map are the same scene at the same size, so they can be compared pixel for pixel rather than by eye.
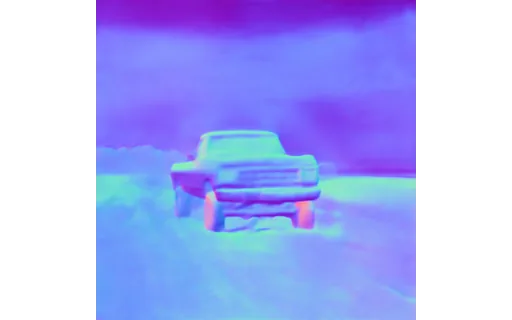
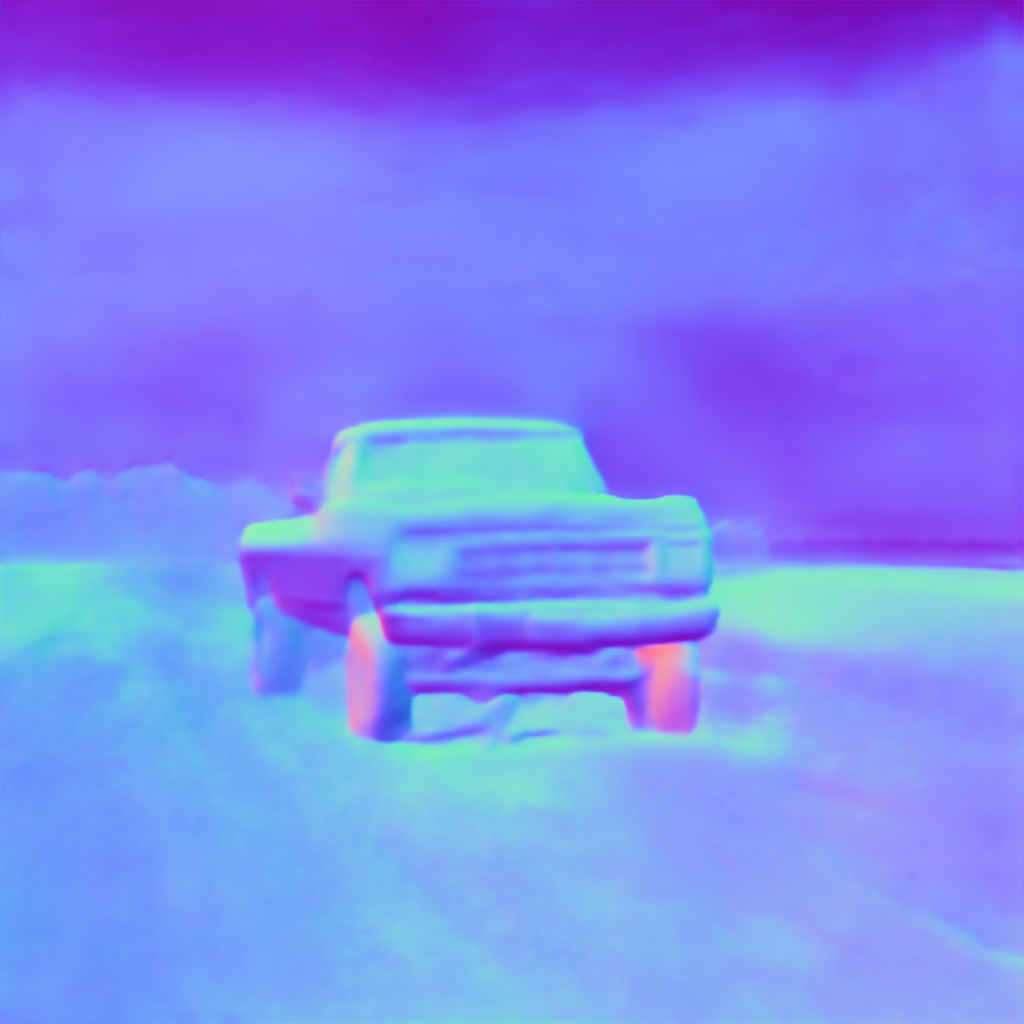
A tangent-space surface normal map for the published plate v-pickup-mud.png, 1024x1024 - the same size as the plate, so the two compare pixel for pixel with no resample in between. RGB encodes the XYZ surface direction remapped from -1..1 into 0..255. Decoded back to vectors this file measures a mean length of 0.9959, which is the number to check your own decode against: a reader that transposes the channels or inverts the remap still produces a plausible-looking image, and lights the surface the wrong way.
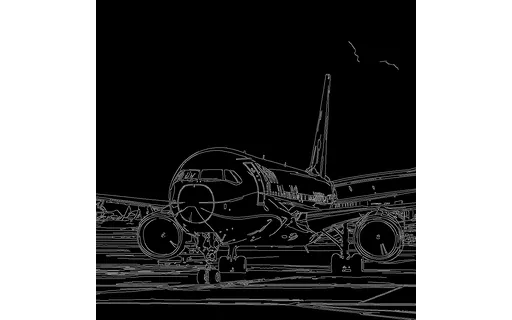
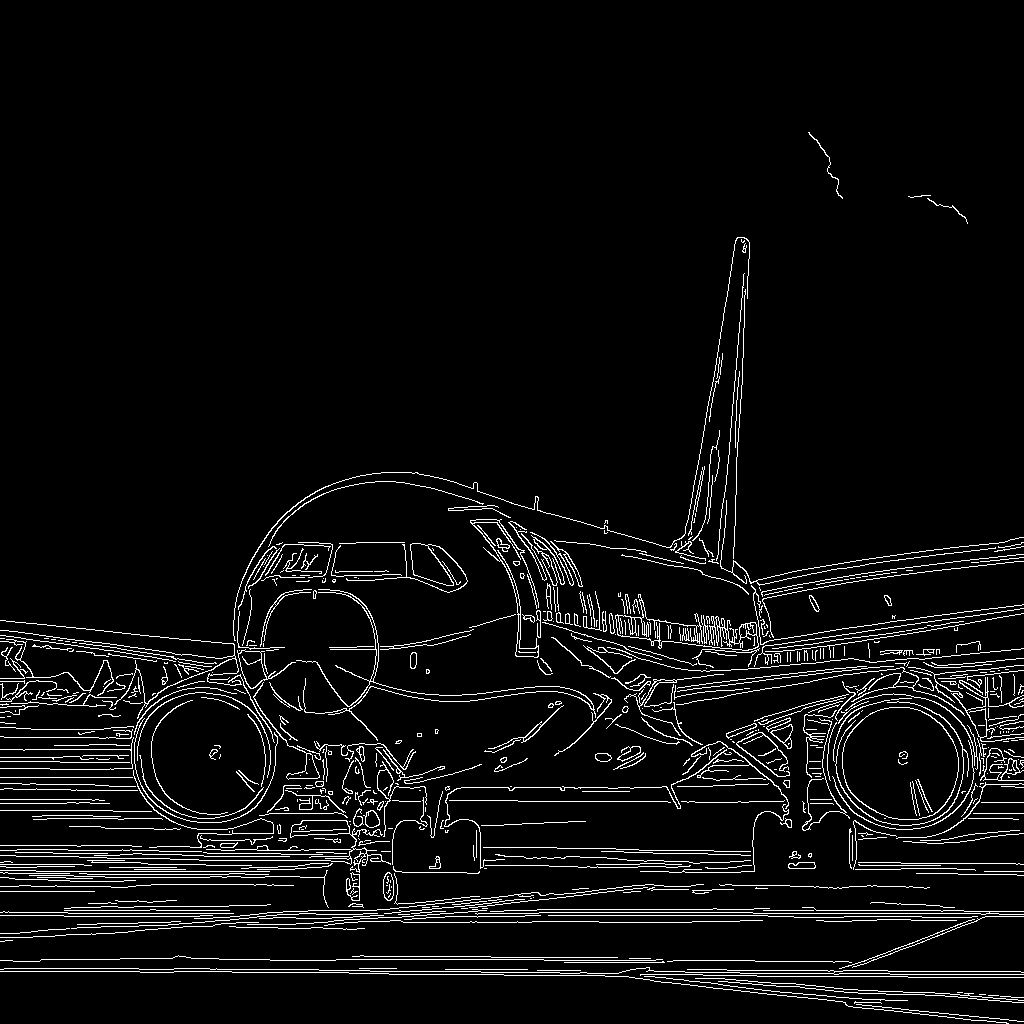
A canny edge map for the published plate v-plane-gate.png, 1024x1024. Canny edge detection at low threshold 0.1 and high 0.3, run at the plate's own resolution so the edges land on the same pixels as the photograph they came from. Lit coverage measures 5.0% of the frame. The plate and this map are the same scene at the same size, so they can be compared pixel for pixel rather than by eye.
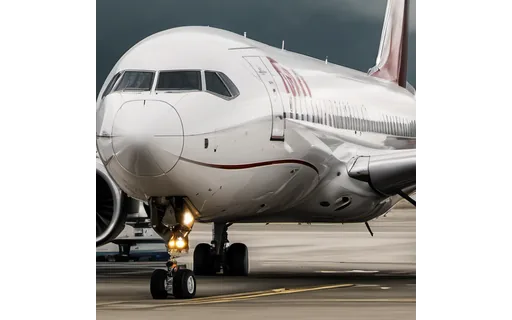
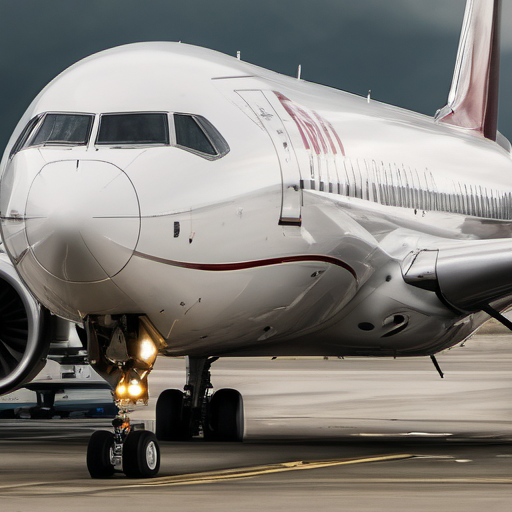
A clean 512x512 crop of passenger aircraft at an airport gate, overcast sky, taken from the published plate v-plane-gate.png before anything was added to it. This is the ANSWER KEY for its group: the object in the source file was composited onto this image, so this is exactly what was behind it. Nothing else in the group came from a second tool's guess.
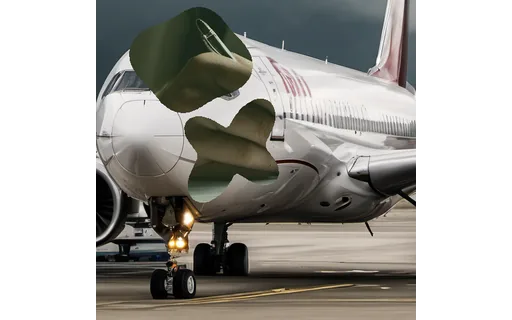
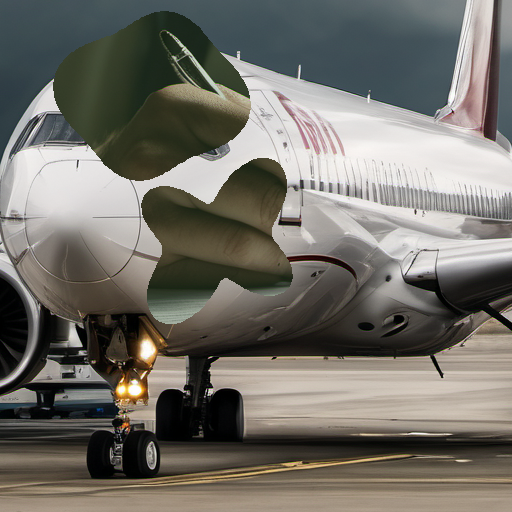
The same view of passenger aircraft at an airport gate, overcast sky, with a foreign object composited over 14.90% of the frame as two disconnected regions - the case a reader that keeps only the largest connected component, or takes the bounding box of both, gets wrong. This is the file an object-removal tool is given. Outside the mask it is byte-identical to the clean plate beside it, so any difference a tool leaves there is damage it did rather than content it was handed.
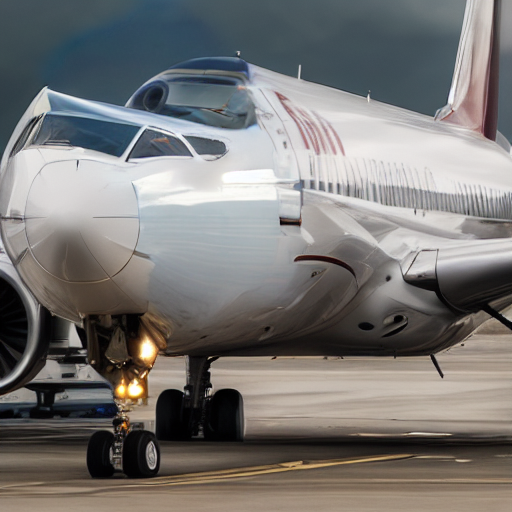
Passenger aircraft at an airport gate, overcast sky, with the object taken back out by Stable Diffusion 1.5 inpainting and the gap reconstructed from the surrounding context alone - the masked latents are erased before sampling, so the model never saw what it was painting over. Inside the mask it differs from the source by 84.008/255 and from the ground-truth plate by 64.23/255; the second number is NOT expected to be small, because an inpainter invents plausible content rather than recovering what was there. Beyond a 16-pixel ring around the mask the frame changes by only 7.224/255, which is the full-frame VAE round trip and not an edit.
The exact footprint of the object sitting over passenger aircraft at an airport gate, overcast sky, as an 8-bit mask covering 14.90% of the frame as two disconnected regions - the case a reader that keeps only the largest connected component, or takes the bounding box of both, gets wrong. It holds only the values 0 and 255. The footprint is what DREW the object, so it is ground truth by construction rather than a segmentation of it. Hard-edged on purpose: a feathered edge has no exact footprint, and the exactness is the point of shipping it.
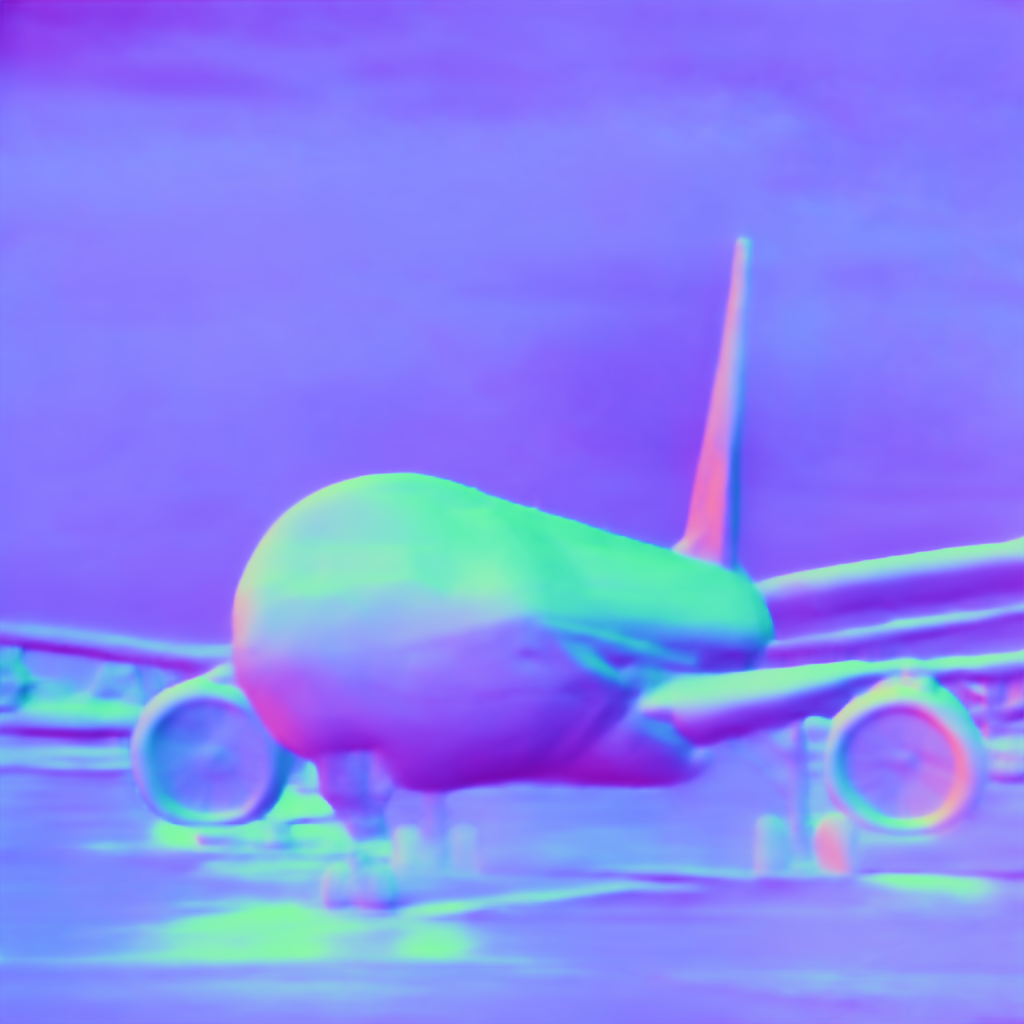
A tangent-space surface normal map for the published plate v-plane-gate.png, 1024x1024 - the same size as the plate, so the two compare pixel for pixel with no resample in between. RGB encodes the XYZ surface direction remapped from -1..1 into 0..255. Decoded back to vectors this file measures a mean length of 0.9958, which is the number to check your own decode against: a reader that transposes the channels or inverts the remap still produces a plausible-looking image, and lights the surface the wrong way.
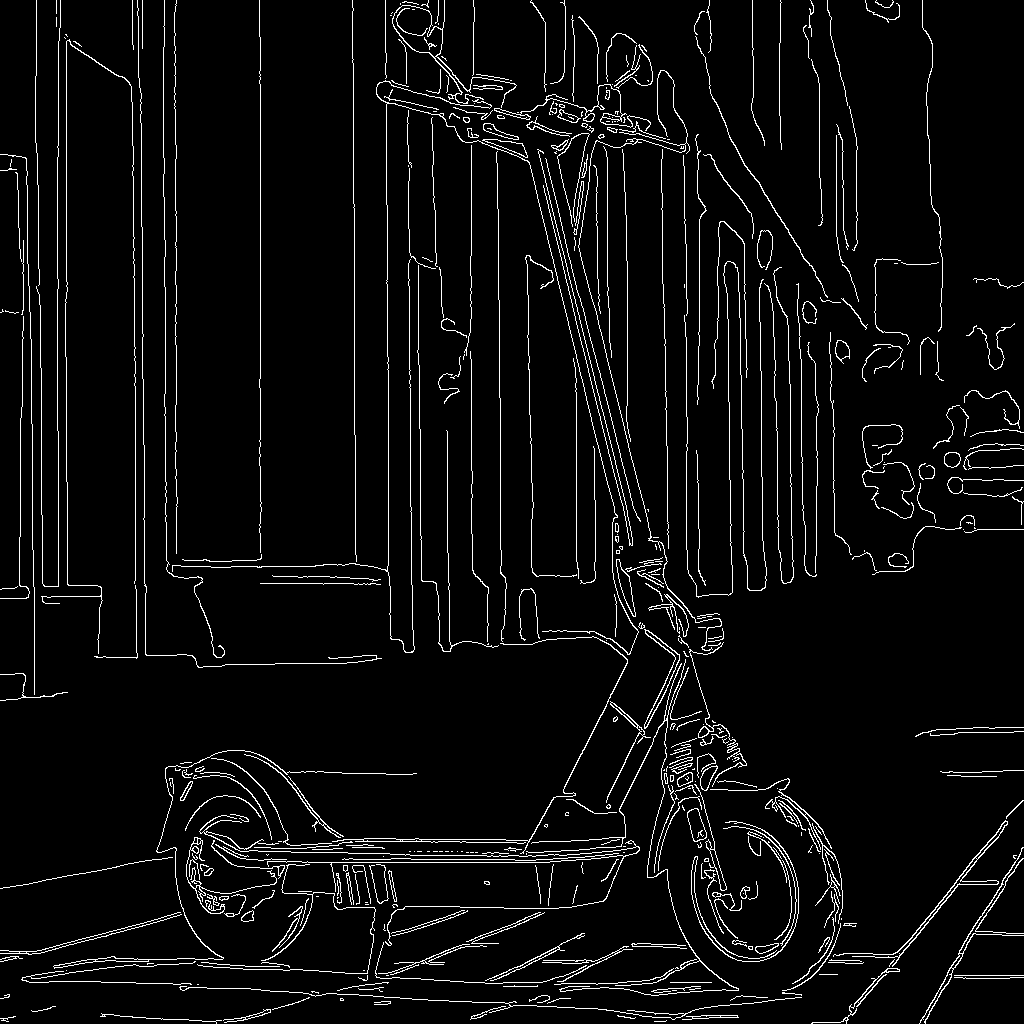
A canny edge map for the published plate v-scooter.png, 1024x1024. Canny edge detection at low threshold 0.1 and high 0.3, run at the plate's own resolution so the edges land on the same pixels as the photograph they came from. Lit coverage measures 4.7% of the frame. The plate and this map are the same scene at the same size, so they can be compared pixel for pixel rather than by eye.
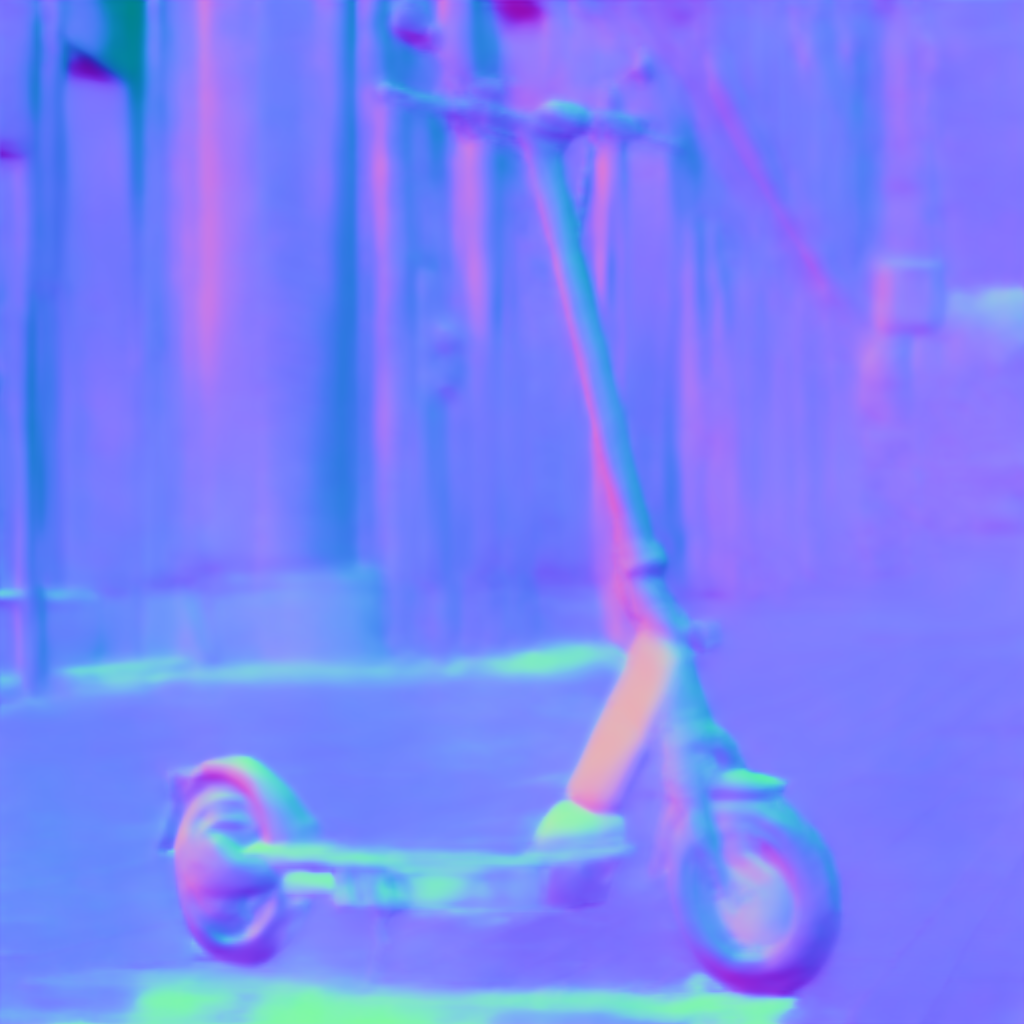
A tangent-space surface normal map for the published plate v-scooter.png, 1024x1024 - the same size as the plate, so the two compare pixel for pixel with no resample in between. RGB encodes the XYZ surface direction remapped from -1..1 into 0..255. Decoded back to vectors this file measures a mean length of 0.9959, which is the number to check your own decode against: a reader that transposes the channels or inverts the remap still produces a plausible-looking image, and lights the surface the wrong way.
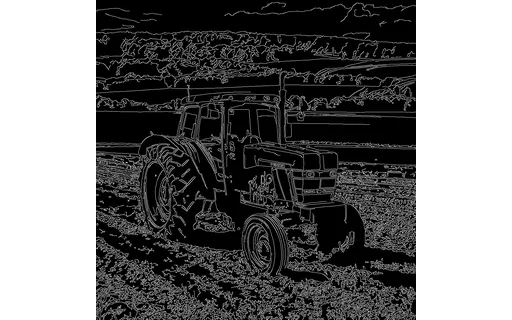
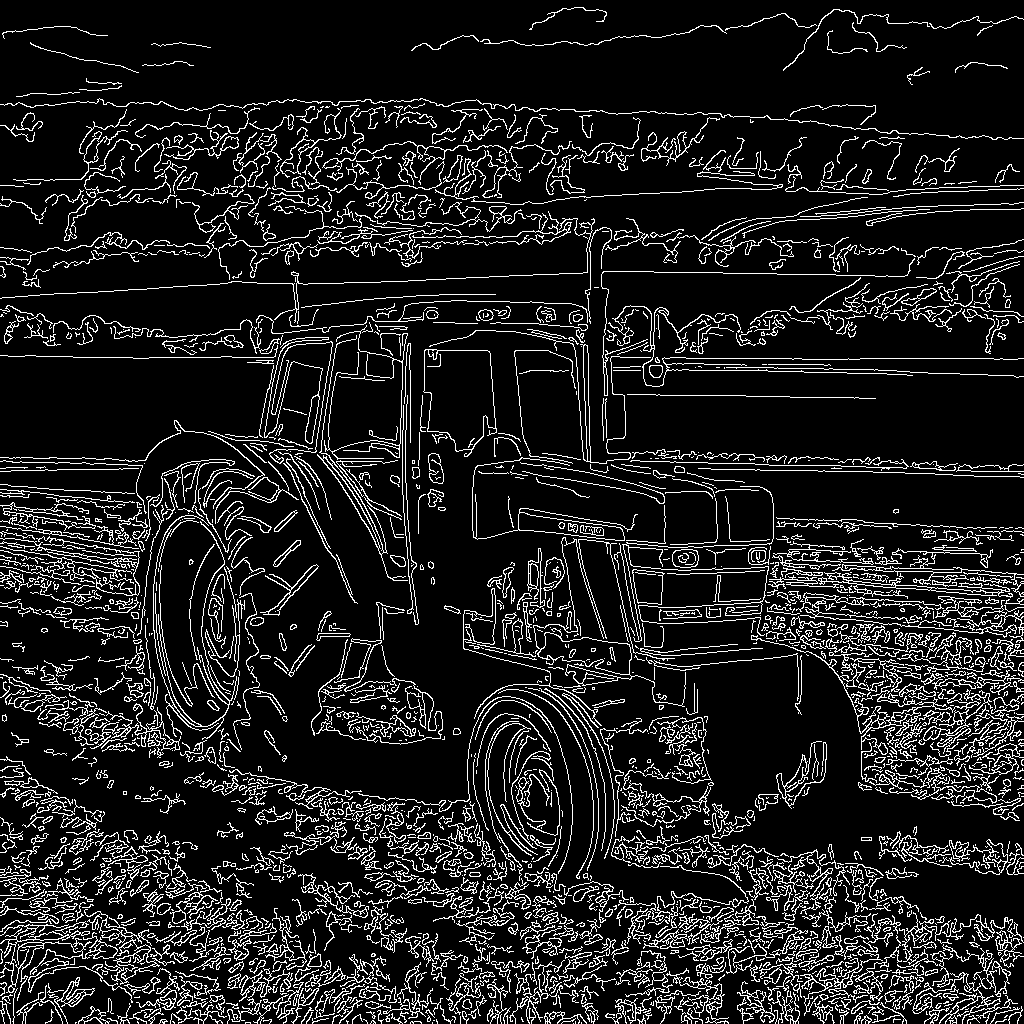
A canny edge map for the published plate v-tractor.png, 1024x1024. Canny edge detection at low threshold 0.1 and high 0.3, run at the plate's own resolution so the edges land on the same pixels as the photograph they came from. Lit coverage measures 12.0% of the frame. The plate and this map are the same scene at the same size, so they can be compared pixel for pixel rather than by eye.
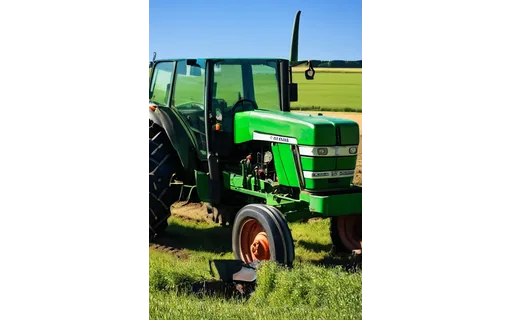
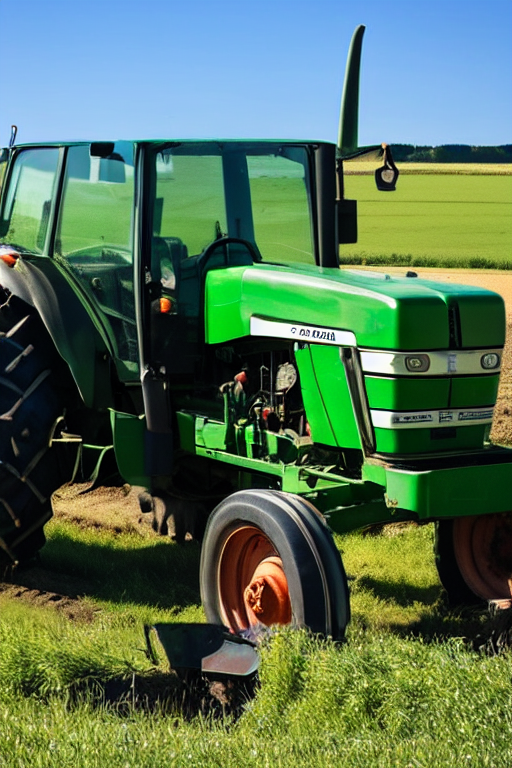
The same view of green farm tractor in a field, blue sky, expanded to 512x768 - 128 pixels added above and below, the symmetric case turned on its side - so 33.3% of this frame is invented canvas. The original sits at pixels 0,128 to 512,640. Compare it INSET by 40 pixels: over that core it differs from the original by only 8.434/255, the VAE round trip, but over the whole rectangle by 14.105/255, because the pad deliberately feathers the original's outer edge into the new area. A test that expects the whole rectangle untouched fails on a correct tool.
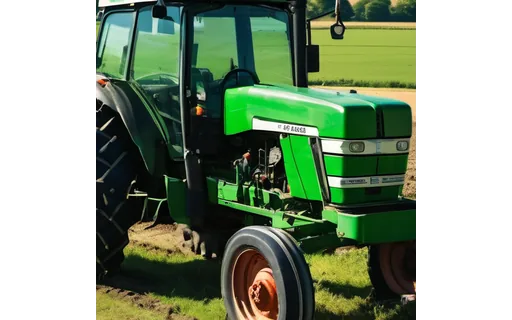
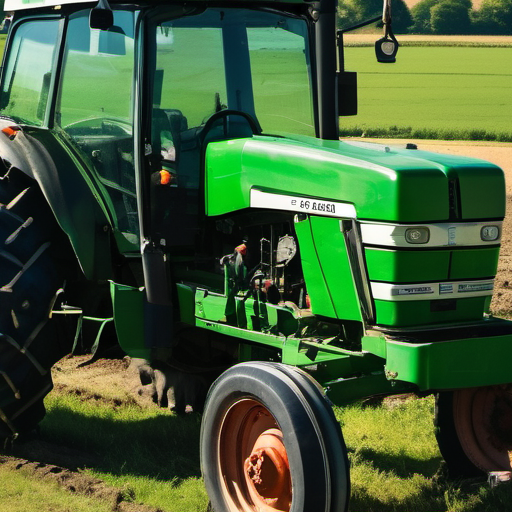
A 512x512 view of green farm tractor in a field, blue sky - the frame an outpainting tool is given, cropped from the published plate nss-v-tractor_00001_.png. Its companion expands it to 512x768 with 128 pixels added above and below, the symmetric case turned on its side, and the boundary record in this group states the exact rectangle this image occupies inside that frame - so where it ended up can be checked rather than eyeballed.
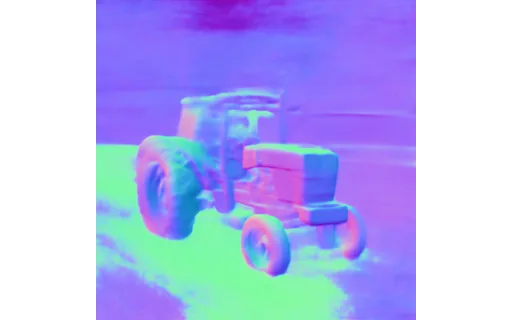
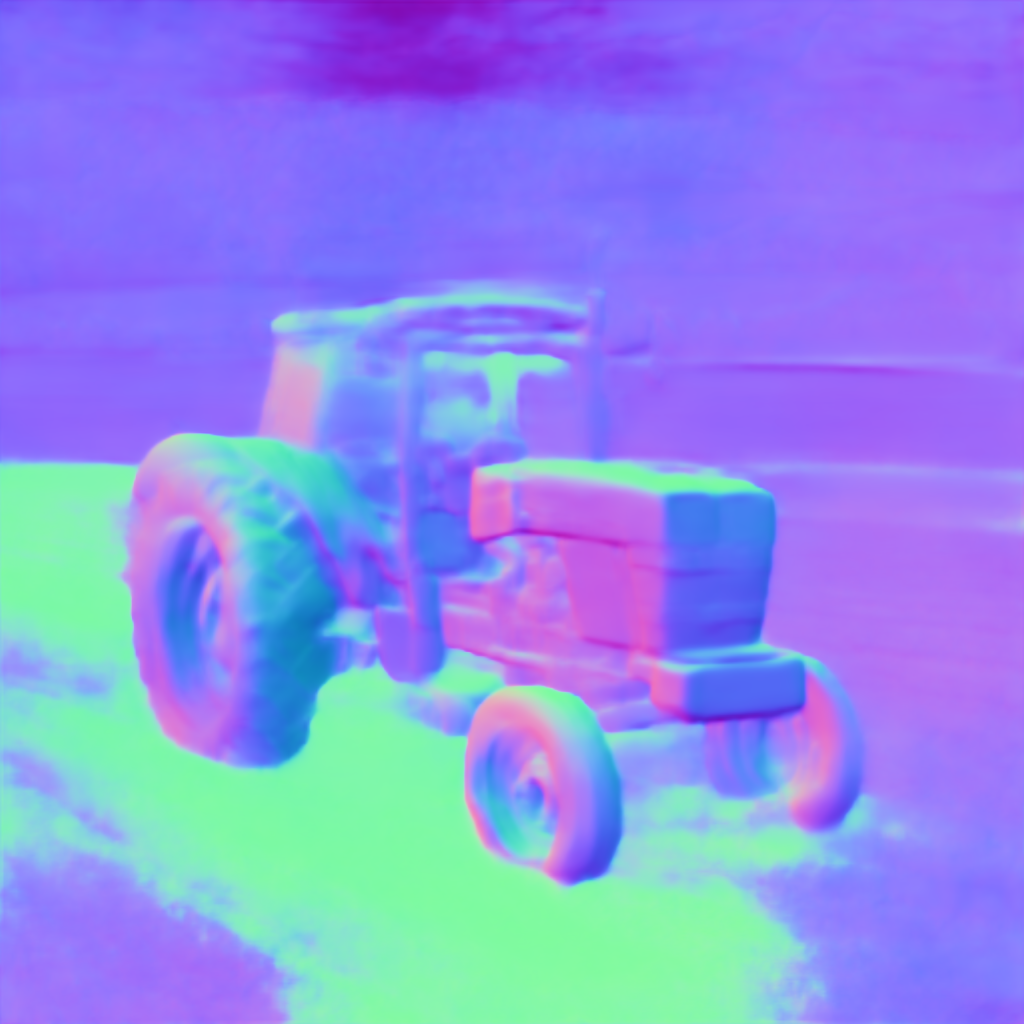
A tangent-space surface normal map for the published plate v-tractor.png, 1024x1024 - the same size as the plate, so the two compare pixel for pixel with no resample in between. RGB encodes the XYZ surface direction remapped from -1..1 into 0..255. Decoded back to vectors this file measures a mean length of 0.9959, which is the number to check your own decode against: a reader that transposes the channels or inverts the remap still produces a plausible-looking image, and lights the surface the wrong way.