Embeddings
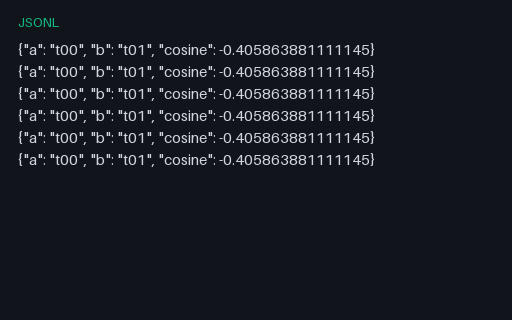
Cosine Similarity Pairs (JSONL)
Precomputed cosine similarity pairs for embedding eval scripts.
- File
- JSONL · Embeddings · 6 records
- Use case
- Model evaluation
The AI category ships the file shapes machine-learning pipelines actually pass around, real formats with documented schemas, all fully synthetic. The NLP set is JSON Lines training data: labelled sentiment, token-level NER with BIO tags, chat fine-tuning in both the OpenAI and Anthropic message shapes (linked as a conversion twin), Alpaca-style instruction tuning, extractive QA in the SQuAD v2 structure with an unanswerable question, abstractive summarization, and an English–Spanish parallel corpus. The embeddings set carries the same 24 texts as an L2-normalised 16-dimensional vector set in three twinned encodings (JSON, Apache Parquet, and a raw NumPy .npy matrix) for testing vector stores and loaders. The vision set renders one detection scene and annotates it three ways (COCO JSON, YOLO text, and Pascal-VOC XML) so you can diff annotation converters against a known image. The evaluation set has benchmark results, a confusion matrix as CSV and JSON twins, an ROC curve, and a scikit-learn-style classification report; there's a templated prompt library, and a genuinely-valid tiny safetensors weight file (sample values, not a trained model). Every dataset uses fixed seeds and invented names, companies, and places, no real people or data.
Filter ai / ml on Browse · 124 files · 10 subcategories
Results start with a representative from each related test family. Use a card’s variant menu or the filters below to reach a specific format, profile, or failure case; every sample retains its own detail page and download.
ASR JSONL, caption/VQA JSONL, mini RAG corpus + queries, semantic-segmentation scene/mask pairs, NER spans, chat prompt turns, plus detection/ranking/tool-calling JSONL and tiny eval packs in later waves.
These are tiny deterministic fixtures for loaders and eval harnesses, not large-scale training corpora.
Filter Browse by purpose tool-calling for function-call JSONL shapes. Treat them as synthetic SAMPLE payloads for schema and harness tests only.
Start with one example from each use-case group, then continue through its other test families. Choose a use case, search, or filter to find a specific profile; a card’s variant menu contains its related samples.
81 test families · 124 available files · Page 1 of 5
Embeddings
Precomputed cosine similarity pairs for embedding eval scripts.
Eval
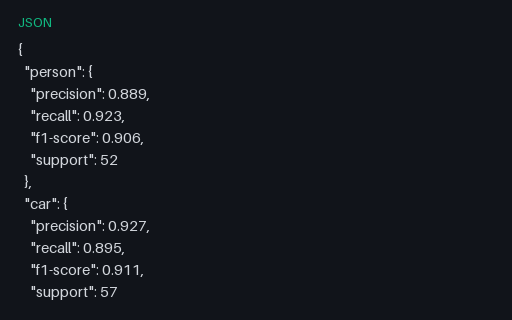
A per-class classification report in the scikit-learn structure: precision, recall, F1, and support for each class plus accuracy and macro/weighted averages. A fixture for testing metric parsers and report renderers.
Model Inference
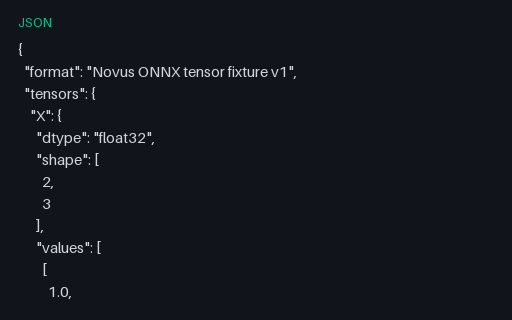
The named float32 input tensor payload for the Affine MatMul plus Add model, with explicit shapes and JSON values for runner-independent test setup.
Nlp
The same synthetic conversations in the Anthropic Messages JSONL shape: a top-level system prompt plus a messages array of user and assistant turns. The format twin of the OpenAI file, for testing chat-format conversion.
Prompts
A single multi-turn chat example for an OCR assistant: system/user/assistant roles in JSONL.
Rag
A short Markdown document in the mini RAG corpus (doc-a.md). Retrieve against the paired queries JSON.
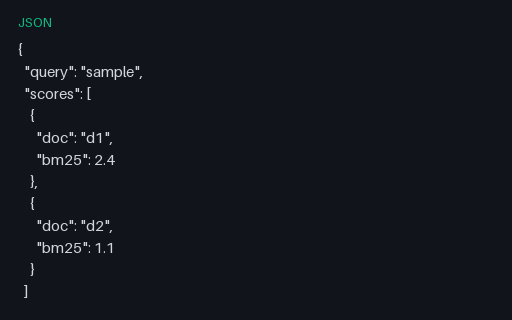
Ranking
BM25 score snapshot for comparing neural rerankers against a lexical baseline.
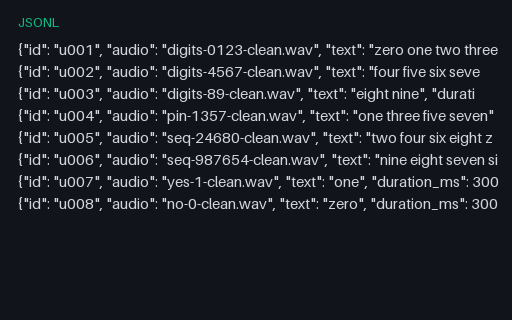
Speech
JSON Lines ASR training/eval set for the Wave B synthetic digit utterances: each row points at a clean WAV and carries the expected transcript.
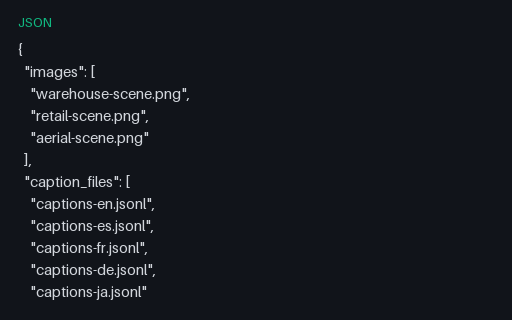
Vision
Manifest linking Wave F scene PNGs to per-language caption JSONL files.
Weights
A genuinely-valid safetensors file with two small float32 tensors (36 parameters total): an 8×4 weight and a length-4 bias. The values are meaningless sample data, not a trained model; a fixture for testing safetensors l
Embeddings
ID list and model metadata for the Wave F embedding set.
Eval
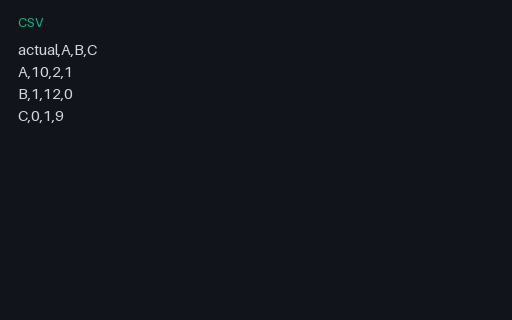
3×3 confusion matrix CSV for classification metric calculators.
Model Inference
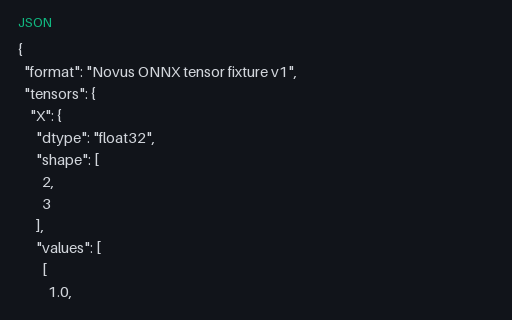
The named float32 input tensor payload for the Dynamic-Batch ReduceSum model, with explicit shapes and JSON values for runner-independent test setup.
Nlp
Hierarchical category labels for taxonomy-aware classifiers.
Prompts
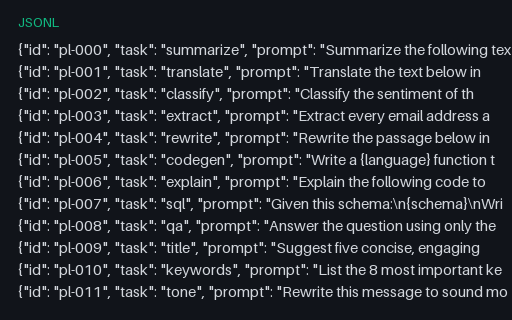
A reusable prompt library in JSON Lines: 20 templated prompts for summarization, translation, extraction, code, and more, each with a task label, tags, and {curly-brace} placeholders. A fixture for prompt-management tool
Ranking
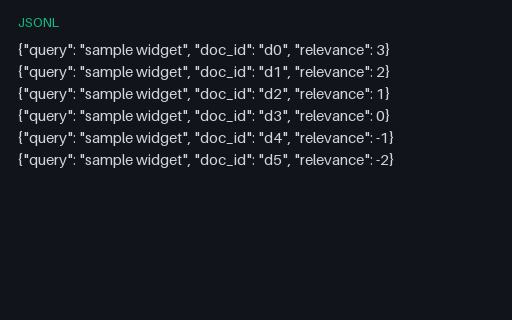
Query-document relevance grades for learning-to-rank training and eval.
Vision
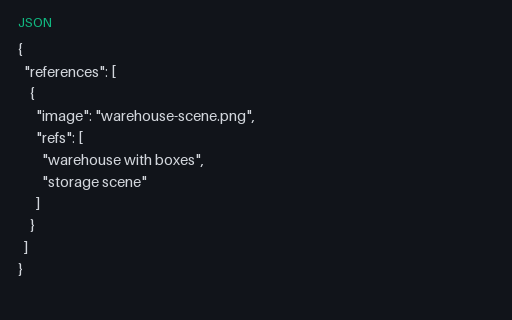
Multiple reference captions per image for BLEU/CIDEr caption eval.
Embeddings
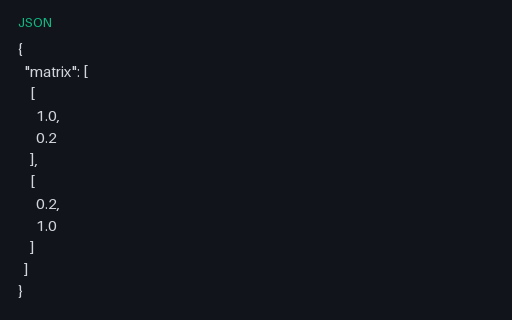
Tiny 2×2 cosine similarity matrix for embedding eval unit tests.
The use-case group filter replaces the long list of category sections.