Skip to content
Testaroo

Training datasets for machine learning

Labelled, synthetic datasets in the shapes ML pipelines expect (JSONL for text tasks, image annotations, embeddings, and sample weights) for testing data loaders, tokenizers, and training tooling.

73 of 73 files
Preview of Recommender Ratings: user/item/rating (CSV, 240 rows)
csv
6.1 KB
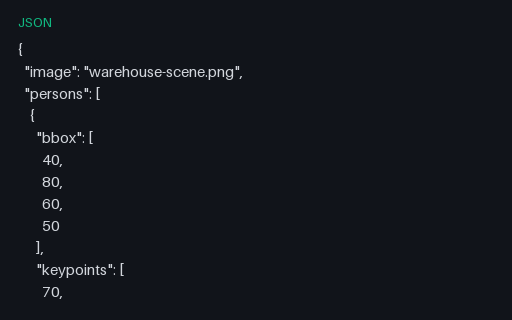
Actual file preview for Recommender Ratings: user/item/rating (CSV, 240 rows)

Recommender Ratings: user/item/rating (CSV, 240 rows)

A MovieLens-style ratings log: 240 user/item/rating events with Unix timestamps across 50 users and 40 items. A fixture for testing recommender pipelines, collaborative-filtering loaders, and sparse-matrix builders.

File
CSV · Recommender · 240 rows
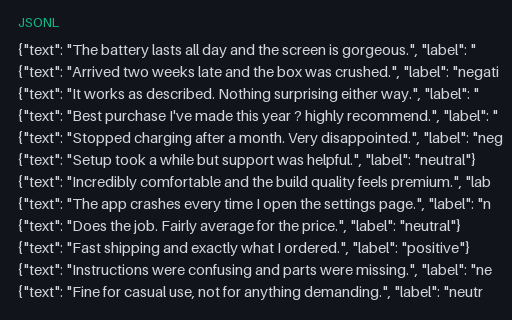
Preview of Sentiment Classification Dataset (JSONL)
jsonl
1.9 KB
Actual file preview for Sentiment Classification Dataset (JSONL)

Sentiment Classification Dataset (JSONL)

A labelled sentiment-classification dataset in JSON Lines: 24 short product-review-style sentences balanced across positive, negative, and neutral. Fully synthetic; a fixture for testing text-classification loaders, tokenizers, and JSONL parsers.

File
JSONL · Nlp · 24 records
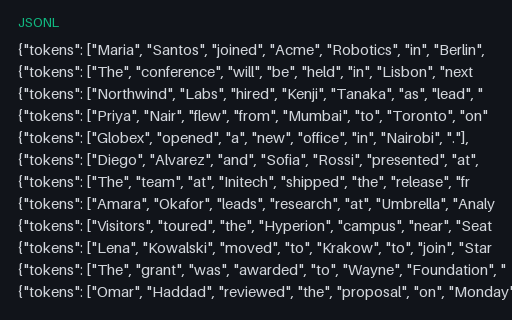
Preview of Named-Entity Recognition Dataset: BIO Tags (JSONL)
jsonl
2.5 KB
Actual file preview for Named-Entity Recognition Dataset: BIO Tags (JSONL)

Named-Entity Recognition Dataset: BIO Tags (JSONL)

A token-classification dataset in JSON Lines: 16 tokenized sentences with aligned BIO tags for person, organisation, and location entities. All names, companies, and places are fictional. A fixture for NER model training and sequence-labelling tooling.

File
JSONL · Nlp · 16 records
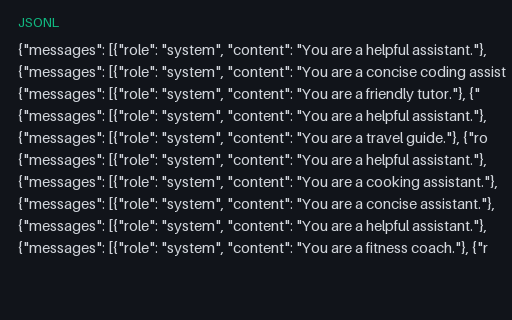
Preview of Chat Fine-tuning Dataset: OpenAI Format (JSONL)
jsonl
2.7 KB
Actual file preview for Chat Fine-tuning Dataset: OpenAI Format (JSONL)

Chat Fine-tuning Dataset: OpenAI Format (JSONL)

A chat fine-tuning dataset in the OpenAI JSONL format: one conversation per line as a messages array with system, user, and assistant turns. Synthetic Q&A content. Paired with an Anthropic-format twin for testing format converters.

File
JSONL · Nlp
Use case
ML training dataNLP datasets+1· Conversion set
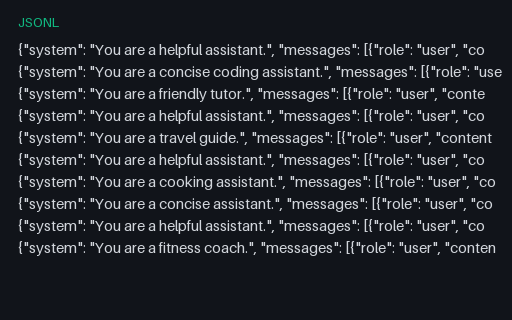
Preview of Chat Fine-tuning Dataset: Anthropic Format (JSONL)
jsonl
2.5 KB
Actual file preview for Chat Fine-tuning Dataset: Anthropic Format (JSONL)

Chat Fine-tuning Dataset: Anthropic Format (JSONL)

The same synthetic conversations in the Anthropic Messages JSONL shape: a top-level system prompt plus a messages array of user and assistant turns. The format twin of the OpenAI file, for testing chat-format conversion.

File
JSONL · Nlp
Use case
ML training dataNLP datasets+1· Conversion set
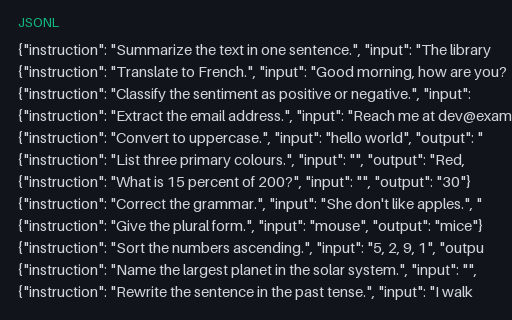
Preview of Instruction-tuning Dataset: Alpaca Format (JSONL)
jsonl
2.1 KB
Actual file preview for Instruction-tuning Dataset: Alpaca Format (JSONL)

Instruction-tuning Dataset: Alpaca Format (JSONL)

An instruction-tuning dataset in the Alpaca JSONL format: 20 instruction / input / output triples covering small transformations, extraction, and factual answers. Fully synthetic; a fixture for supervised fine-tuning pipelines.

File
JSONL · Nlp · 20 records
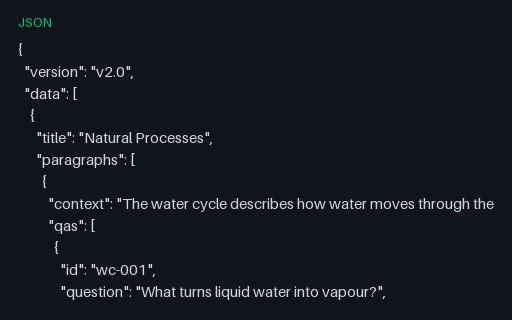
Preview of Extractive QA Dataset: SQuAD v2 Format (JSON)
json
2.2 KB
Actual file preview for Extractive QA Dataset: SQuAD v2 Format (JSON)

Extractive QA Dataset: SQuAD v2 Format (JSON)

An extractive question-answering dataset in the SQuAD v2.0 JSON structure, titled articles with context paragraphs, questions, character-offset answers, and one deliberately unanswerable question. Synthetic content; a fixture for QA model training and SQuAD-format loaders.

File
JSON · Nlp
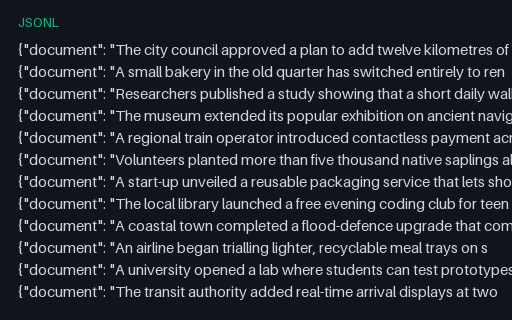
Preview of Summarization Dataset (JSONL)
jsonl
5.1 KB
Actual file preview for Summarization Dataset (JSONL)

Summarization Dataset (JSONL)

An abstractive-summarization dataset in JSON Lines: 15 short synthetic news-style documents each paired with a one-sentence summary. A fixture for training and evaluating summarization models and for testing JSONL ingestion.

File
JSONL · Nlp · 15 records
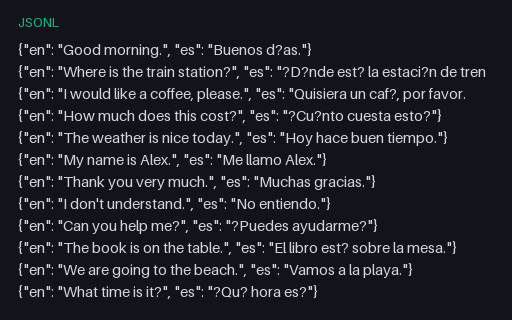
Preview of Parallel Translation Corpus: EN↔ES (JSONL)
jsonl
1.3 KB
Actual file preview for Parallel Translation Corpus: EN↔ES (JSONL)

Parallel Translation Corpus: EN↔ES (JSONL)

An English↔Spanish parallel corpus in JSON Lines: 20 aligned sentence pairs of everyday phrases. A fixture for training and evaluating machine-translation models and for testing UTF-8 handling of accented characters.

File
JSONL · Nlp
Preview of Text Embeddings: 16-dim (JSON)
json
13.5 KB
Actual file preview for Text Embeddings: 16-dim (JSON)

Text Embeddings: 16-dim (JSON)

A set of 24 L2-normalised 16-dimensional text embeddings as JSON: each record pairs an id and its source text with a float vector. A fixture for testing vector stores, similarity search, and embedding loaders. Parquet and .npy twins included.

File
JSON · Embeddings · 24 records
Use case
ML training dataEmbeddings+2· Conversion set
Preview of Text Embeddings: 16-dim (Parquet)
parquet
9.3 KB
Actual file preview for Text Embeddings: 16-dim (Parquet)

Text Embeddings: 16-dim (Parquet)

The same 16-dimensional embeddings as Apache Parquet: id and text columns plus one column per dimension. The columnar twin, for testing analytics engines and Parquet-based vector pipelines.

File
PARQUET · Embeddings · 24 rows
Use case
ML training dataEmbeddings+2· Conversion set
Preview of Text Embeddings: 24×16 matrix (NumPy .npy)
npy
1.6 KB
Actual file preview for Text Embeddings: 24×16 matrix (NumPy .npy)

Text Embeddings: 24×16 matrix (NumPy .npy)

The embeddings as a raw NumPy array: a 24×16 float32 matrix in .npy format, loadable with numpy.load. The binary twin of the JSON and Parquet files, for testing tensor and matrix loaders.

File
NPY · Embeddings
Use case
ML training dataEmbeddings+1· Conversion set
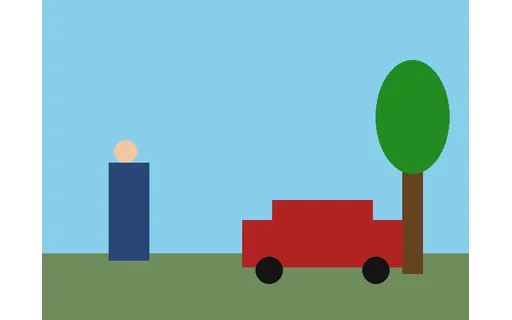
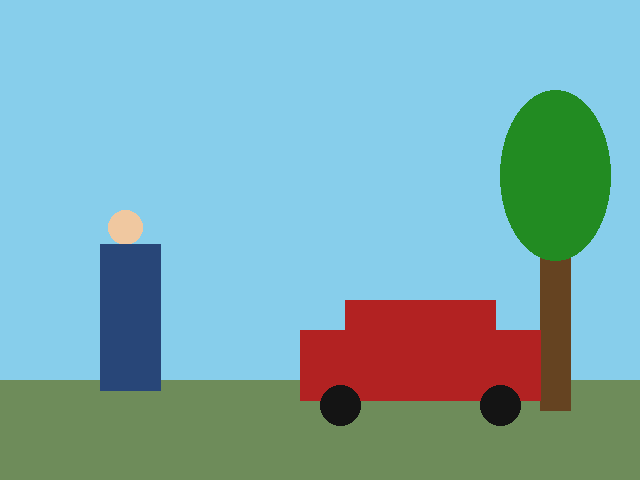
Preview of Object-detection Scene (PNG, 640×480)
png
2.9 KB
Actual file preview for Object-detection Scene (PNG, 640×480)

Object-detection Scene (PNG, 640×480)

A simple rendered street scene with a person, a car, and a tree at known pixel coordinates: the image the COCO, YOLO, and Pascal-VOC annotation twins describe. A fixture for testing object-detection loaders and annotation converters.

File
PNG · Vision · 640 × 480 px
Preview of Detection Class List (TXT)
txt
19 B
Actual file preview for Detection Class List (TXT)

Detection Class List (TXT)

The class-name list for the detection scene, one label per line: index equals the zero-based line number, matching the YOLO class ids. A companion to the COCO/YOLO/VOC annotation files.

File
TXT · Vision
Preview of Detection Annotations: COCO (JSON)
json
1 KB
Actual file preview for Detection Annotations: COCO (JSON)

Detection Annotations: COCO (JSON)

Object-detection annotations for the scene in the COCO JSON format: images, categories, and per-object bounding boxes as [x, y, width, height]. Grouped with YOLO and Pascal-VOC twins for testing annotation-format conversion.

File
JSON · Vision
Use case
Computer visionML training data+2· Conversion set
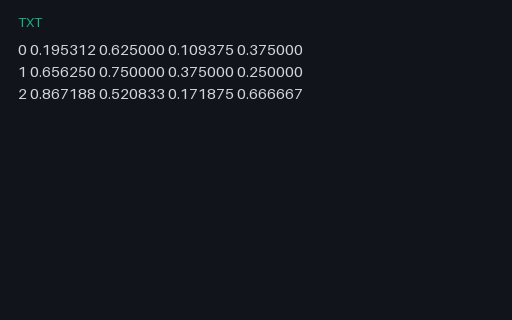
Preview of Detection Annotations: YOLO (TXT)
txt
117 B
Actual file preview for Detection Annotations: YOLO (TXT)

Detection Annotations: YOLO (TXT)

The same detection boxes in the YOLO text format: one object per line as class id and box centre, width, and height normalised to 0–1. The format twin of the COCO and VOC annotations.

File
TXT · Vision
Use case
Computer visionML training data+1· Conversion set
Preview of Detection Annotations: Pascal VOC (XML)
xml
1 KB
Actual file preview for Detection Annotations: Pascal VOC (XML)

Detection Annotations: Pascal VOC (XML)

The same detection boxes in the Pascal VOC XML format: a per-image annotation with size, and one object element per box with pixel corner coordinates. The XML twin of the COCO and YOLO annotations.

File
XML · Vision
Use case
Computer visionML training data+1· Conversion set
Preview of Tiny Model Weights (safetensors)
safetensors
365 B
Actual file preview for Tiny Model Weights (safetensors)

Tiny Model Weights (safetensors)

A genuinely-valid safetensors file with two small float32 tensors (36 parameters total): an 8×4 weight and a length-4 bias. The values are meaningless sample data, not a trained model; a fixture for testing safetensors loaders and weight inspectors.

File
SAFETENSORS · Weights
Preview of ASR Digit Utterances Dataset (JSONL)
jsonl
764 B
Actual file preview for ASR Digit Utterances Dataset (JSONL)

ASR Digit Utterances Dataset (JSONL)

JSON Lines ASR training/eval set for the Wave B synthetic digit utterances: each row points at a clean WAV and carries the expected transcript.

File
JSONL · Speech · 8 records