Ranking
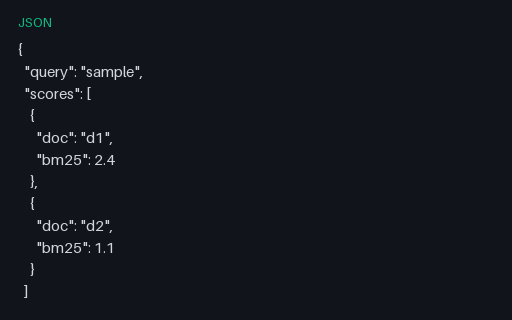
BM25 Retrieval Scores (JSON)
BM25 score snapshot for comparing neural rerankers against a lexical baseline.
- File
- JSON · Ranking
- Use case
- Model evaluation / JSON parsing
Benchmark results, confusion matrices, ROC curves, and classification reports in CSV and JSON, for testing eval dashboards, metric parsers, and leaderboard importers.
Each card starts with one representative test file. Choose a use case, search, or filter to find a specific profile; a card’s variant menu contains its related samples.
25 test families · 40 available files · Page 1 of 2
Ranking
BM25 score snapshot for comparing neural rerankers against a lexical baseline.
Vision
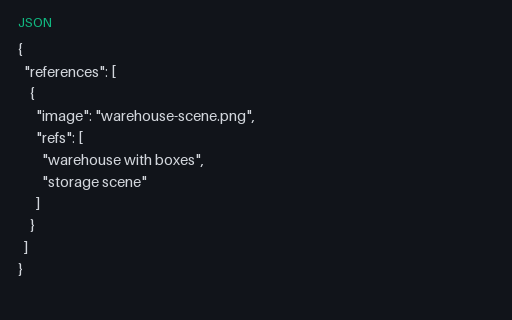
Multiple reference captions per image for BLEU/CIDEr caption eval.
Eval
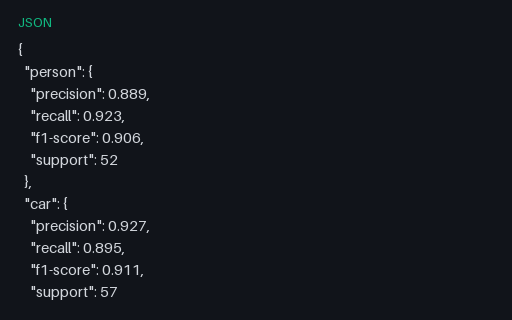
A per-class classification report in the scikit-learn structure: precision, recall, F1, and support for each class plus accuracy and macro/weighted averages. A fixture for testing metric parsers and report renderers.
Eval
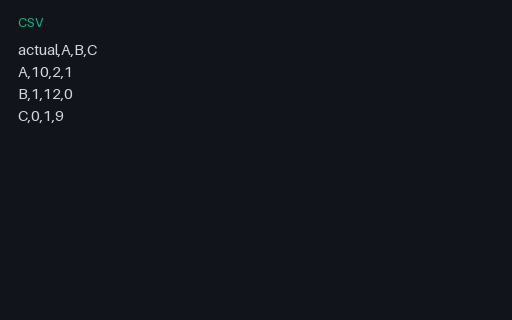
3×3 confusion matrix CSV for classification metric calculators.
Eval
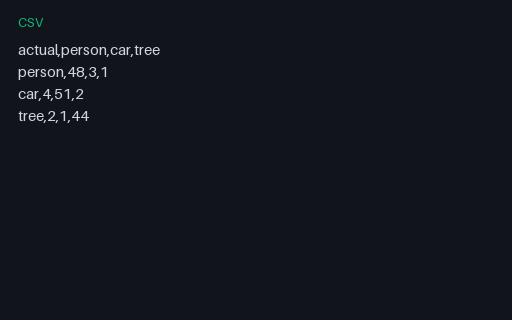
A 3-class confusion matrix as CSV: rows are the true class, columns the predicted class, cells the counts. Paired with a JSON twin for testing metric parsers and evaluation visualisers.
Eval
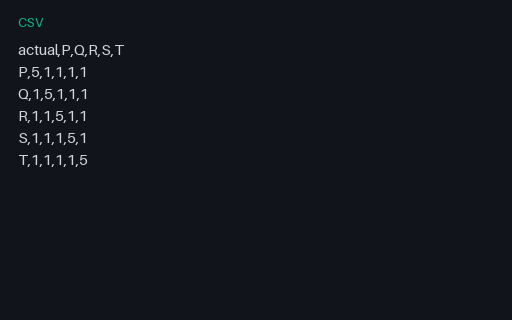
5×5 confusion matrix with off-diagonal noise for multi-class eval.
Embeddings
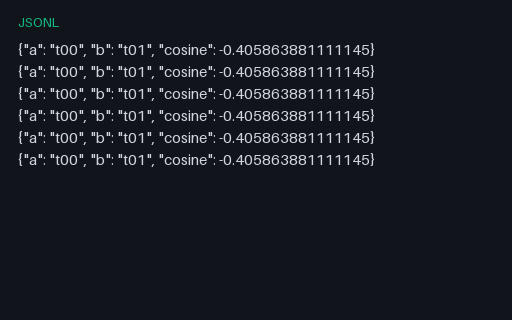
Precomputed cosine similarity pairs for embedding eval scripts.
Eval
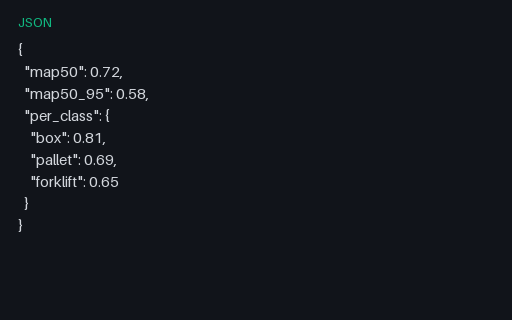
Synthetic mAP evaluation summary for object-detection benchmark harness tests.
Embeddings
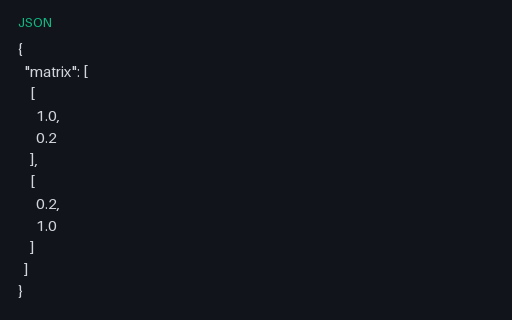
Tiny 2×2 cosine similarity matrix for embedding eval unit tests.
Eval
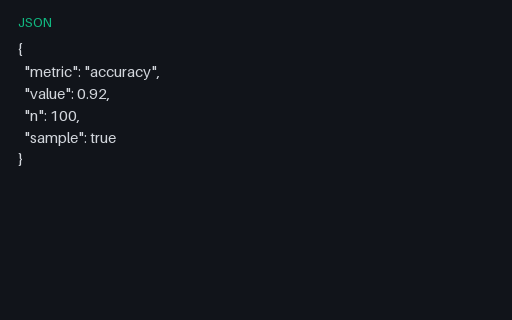
Minimal SAMPLE eval metric JSON (accuracy) for dashboard parsers.
Eval
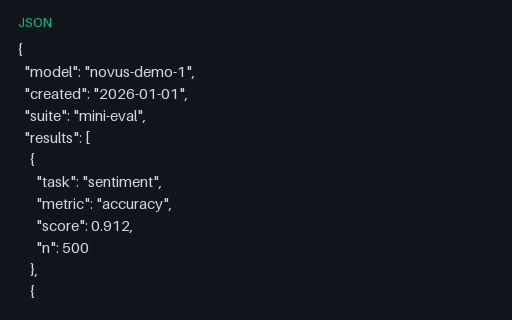
A model-evaluation summary in JSON, per-task scores for a fictional model across sentiment, NER, summarization, translation, and QA, each with its metric and sample size. A fixture for testing eval dashboards and leaderb
Ranking
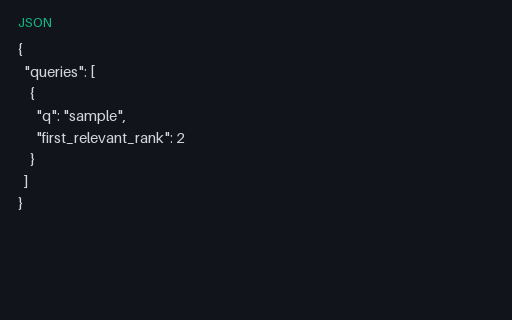
Mean reciprocal rank ground truth for search eval harness tests.
Ranking
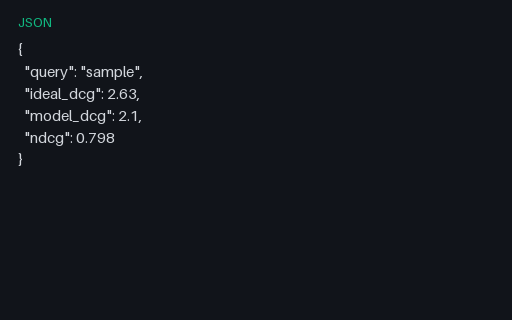
Precomputed DCG/nDCG values for ranking metric unit tests.
Model Inference
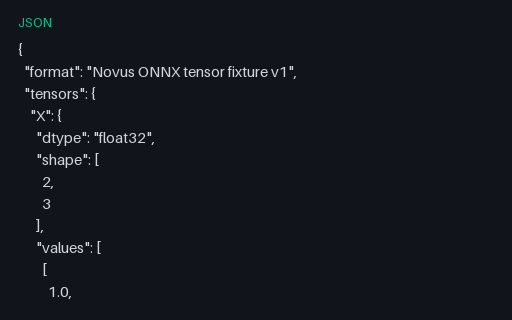
The named float32 input tensor payload for the Affine MatMul plus Add model, with explicit shapes and JSON values for runner-independent test setup.
Model Inference
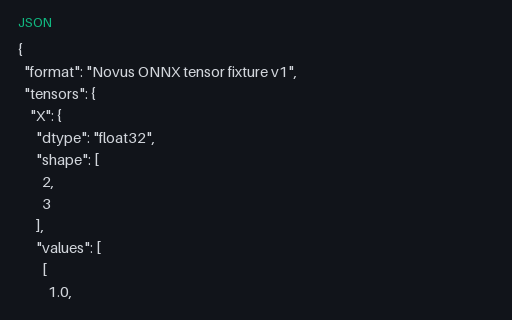
The named float32 input tensor payload for the Dynamic-Batch ReduceSum model, with explicit shapes and JSON values for runner-independent test setup.
Model Inference
The named float32 input tensor payload for the Static Identity model, with explicit shapes and JSON values for runner-independent test setup.
Model Inference
The reference-evaluator output for the Two-Input Broadcast Add model and supplied input, including shape, dtype, exact values and a 1e-6 tolerance.
Eval
Per-class precision/recall/F1 snapshot for classification dashboards.