Parquet: Columnar Table
A small employee table as Apache Parquet: the columnar format at the heart of modern data lakes and analytics. For testing Parquet readers (pandas, Spark, DuckDB) and conversion.
| idint64 | namestring | emailstring | departmentstring | activebool | scoredouble | joineddate |
|---|---|---|---|---|---|---|
| 1001 | Ada Lovelace | ada.lovelace@example.com | Engineering | true | 98.5 | 2021-03-01 |
| 1002 | Alan Turing | alan.turing@example.com | Research | true | 95 | 2020-06-15 |
| 1003 | Grace Hopper | grace.hopper@example.com | Engineering | false | 91.2 | 2019-11-20 |
| 1004 | Katherine Johnson | katherine.johnson@example.com | Operations | true | 96.8 | 2022-01-10 |
| 1005 | Edsger Dijkstra | edsger.dijkstra@example.com | Research | false | 89.4 | 2018-09-05 |
Specifications
- Rows
- 5
- Columns
- 7
- Format
- Apache Parquet
- Layout
- columnar
- Compression
- snappy
Testing contract
Expected to pass- Scenario
- Exercise Parquet: Columnar Table in its binary workflow. A small employee table as Apache Parquet: the columnar format at the heart of modern data lakes and analytics.
- Expected result
- 5 rows, 7 columns; fields: id: int64; name: string; email: string; department: string; active: bool; score: double; joined: string; column null counts=[0, 0, 0, 0, 0, 0, 0]. Declared feature checks: columns=7; layout=columnar; compression=snappy.
What is a .parquet file?
Apache Parquet (.parquet) is a binary, columnar storage format for analytical data. It stores each column separately with per-column compression and encoding, embeds a schema and statistics, and is the de-facto standard for data lakes and engines like Spark, DuckDB, and pandas/pyarrow.
How to use this file
Use an example .parquet file to test columnar readers (pyarrow, DuckDB, Spark), schema and predicate-pushdown handling, and Parquet-to-CSV/JSON converters.
How to use this file for testing
“Parquet: Columnar Table” is a deterministic Testaroo fixture for Conversion testing, Data engineering. The same content exported across many formats and linked as a group, so you can convert one and diff against the expected twin.
Documented properties for this file: 5 rows · 7 columns · Apache Parquet. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Code examples
import pandas as pd  # pip install pyarrow

df = pd.read_parquet("employees.parquet")
print(df.head())
print(df.dtypes)
Generated by generation/data_binary.py. Free for any use, no attribution required, license.
Related files
- h5HDF5: Hierarchical Scientific DataA small HDF5 file with a compound 'employees' dataset and a numeric 'readings' grid: the hierarchical format used across science and ML. For testing h5py/HDF5 readers and conversion.
- orcConvert v2 ORC Employee Table SourceBinary orc source for the five-row P8 employee conversion table, preserving ids, names, departments, booleans, and scores. Stable P8 artifact p8-convert-orc-source.
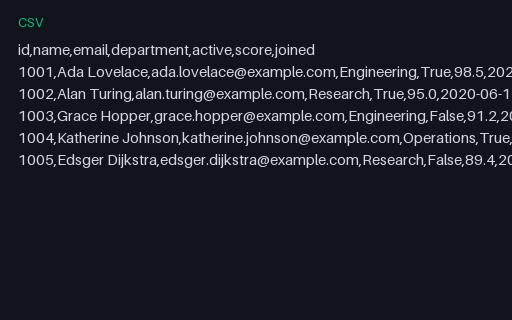
- csvConvert v2 ORC Expected CSVCsv semantic reference for the five-row P8 employee conversion table, preserving ids, names, departments, booleans, and scores. Stable P8 artifact p8-convert-orc-csv.
- jsonConvert v2 ORC Expected JSONJson semantic reference for the five-row P8 employee conversion table, preserving ids, names, departments, booleans, and scores. Stable P8 artifact p8-convert-orc-json.
- csvE-commerce Customers (CSV, 500 rows)A realistic e-commerce customer directory (500 rows): part of a relational dataset (products, customers, orders) with CSV, JSON, SQL, and Parquet twins for testing joins, imports, and conversion.
- csvE-commerce Orders (CSV, 2000 rows)A realistic e-commerce order lines (customer_id → customers, product_id → products) (2000 rows): part of a relational dataset (products, customers, orders) with CSV, JSON, SQL, and Parquet twins for testing joins, imports, and conversion.