EML Header: Content Language
SAMPLE .eml focusing on content language header behaviour.
From: Alex SAMPLE <alex@brightside.example>
To: Sam Rivera <sam@meridiansupply.example>
Subject: Content-Language SAMPLE
Date: Wed, 22 Jul 2026 09:30:00 -0400
Message-ID: <wi-clang@brightside.example>
Content-Language: en-US
MIME-Version: 1.0
Content-Type: text/plain; charset=utf-8

Language-tagged SAMPLE body.
Specifications
- Role
- header-variant
- Wave
- I
Testing contract
Expected to pass- Scenario
- Exercise EML Header: Content Language in its headers workflow. SAMPLE .eml focusing on content language header behaviour.
- Expected result
- subject='Content-Language SAMPLE'; content type=text/plain; MIME leaf parts=1. Declared feature checks: role=header-variant.
What is a .eml file?
An EML file is a single email message stored in the RFC 822 / MIME format: plain-text headers (From, To, Subject, Date, Message-ID) followed by the body, which may be plain text, HTML, or a multipart structure with alternative bodies and file attachments encoded in base64.
How to use this file
Use an example EML to test email header parsing, MIME decoding, HTML-part handling, attachment extraction, and EML-to-other-format conversion.
How to use this file for testing
“EML Header: Content Language” is a deterministic Testaroo fixture for Email parsing. Standards-compliant RFC 822 messages (plain, multipart text+HTML, and with an attachment) plus an MBOX mailbox, for testing header parsing, MIME decoding, attachment extraction, and mailbox splitting.
Documented properties for this file: header-variant. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Email fixtures use fixed dates, message IDs, and MIME boundaries so runs are reproducible, and every address is fictional. Test header parsing, MIME decoding, attachment extraction, and EML/MBOX conversion against the documented structure.
Code examples
from email import policy
from email.parser import BytesParser

msg = BytesParser(policy=policy.default).parse(open("content-language.eml", "rb"))
print(msg["subject"], msg["from"])
Generated by generation/pad_wave_i.py. Free for any use, no attribution required, license.
Related files
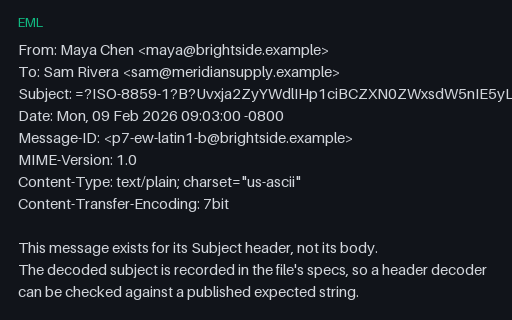
- emlEML, RFC 2047 Subject: ISO-8859-1 'B' EncodingThe ISO-8859-1 Subject again, base64-encoded instead of Q-encoded. Base64 hides the charset entirely, so this is the fixture that catches a decoder guessing the charset from the octets instead of reading the encoded-word's charset token.
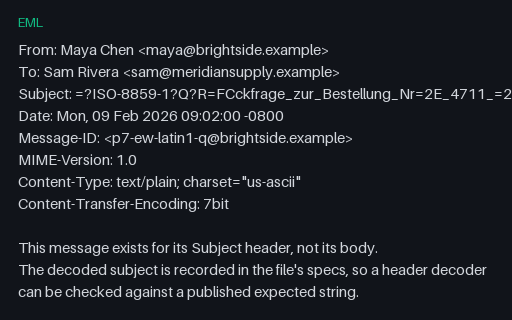
- emlEML, RFC 2047 Subject: ISO-8859-1 'Q' EncodingA German Subject encoded as ISO-8859-1 'Q', the shape most legacy mail actually uses. Each umlaut is one =XX escape, so a decoder that assumes UTF-8 produces mojibake rather than a clean error.
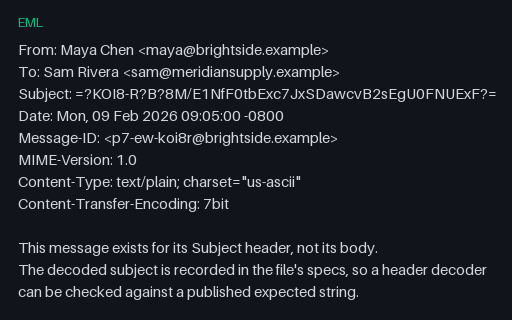
- emlEML, RFC 2047 Subject: KOI8-R 'B' EncodingA Russian Subject as a KOI8-R base64 encoded-word. KOI8-R orders Cyrillic letters by Latin transliteration rather than alphabetically, so a decoder that substitutes any other Cyrillic codepage returns readable-looking but wrong text.
- emlEML, RFC 2047 Subject: Shift_JIS 'B' EncodingA Japanese Subject as a Shift_JIS base64 encoded-word. Shift_JIS second bytes overlap ASCII punctuation values, so a decoder that scans the decoded octets for delimiters before converting the charset splits the string in the wrong place.
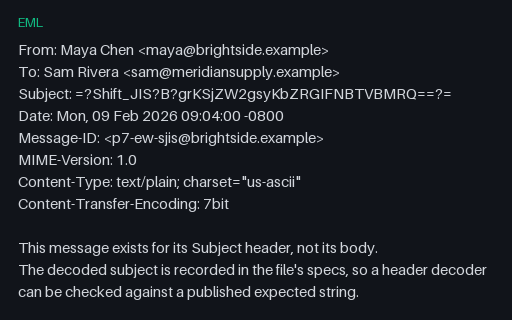
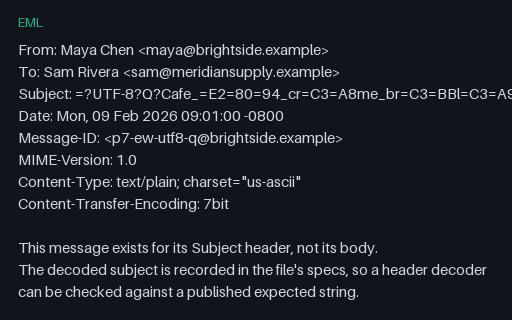
- emlEML, RFC 2047 Subject: UTF-8 'B' EncodingA Subject header carrying accented Latin text and an emoji as a single UTF-8 base64 encoded-word. Its Q-encoded twin decodes to the identical string, so the two together isolate the encoding from the charset.
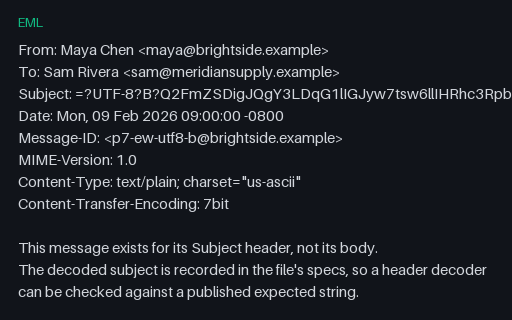
- emlEML, RFC 2047 Subject: UTF-8 'Q' EncodingThe same Subject as the UTF-8 'B' twin, written with 'Q' encoding instead: underscores stand for spaces and every non-token octet is an =XX escape. A decoder that forgets the underscore rule produces visibly different text from its twin.