Text Embeddings: 16-dim (Parquet)
The same 16-dimensional embeddings as Apache Parquet: id and text columns plus one column per dimension. The columnar twin, for testing analytics engines and Parquet-based vector pipelines.
| id | text | emb_00 | emb_01 | emb_02 |
|---|---|---|---|---|
| doc-000 | The battery lasts all day and the sc… | -0.07038400322198868 | -0.09160999953746796 | 0.24376200139522552 |
| doc-001 | Arrived two weeks late and the box w… | -0.029543999582529068 | 0.25906801223754883 | 0.16588300466537476 |
| doc-002 | It works as described. Nothing surpr… | -0.24579299986362457 | -0.40040600299835205 | -0.05987099930644035 |
| doc-003 | Best purchase I've made this year — … | 0.2533159852027893 | 0.08270400017499924 | 0.0461140014231205 |
| doc-004 | Stopped charging after a month. Very… | 0.12307199835777283 | 0.08135800063610077 | 0.038029998540878296 |
| doc-005 | Setup took a while but support was h… | -0.07104899734258652 | -0.10132499784231186 | 0.09806299954652786 |
| doc-006 | Incredibly comfortable and the build… | -0.06588000059127808 | 0.14317099750041962 | 0.3456229865550995 |
| doc-007 | The app crashes every time I open th… | 0.020137999206781387 | -0.0990620031952858 | 0.07678800076246262 |
Specifications
- Rows
- 24
- Columns
- 18
- Dimensions
- 16
- Format
- Apache Parquet
- Seed
- 1729
Testing contract
Expected to pass- Scenario
- Exercise Text Embeddings: 16-dim (Parquet) in its embeddings workflow. The same 16-dimensional embeddings as Apache Parquet: id and text columns plus one column per dimension.
- Expected result
- 24 rows, 18 columns; fields: id: string; text: string; emb_00: double; emb_01: double; emb_02: double; emb_03: double; emb_04: double; emb_05: double; emb_06: double; emb_07: double; emb_08: double; emb_09: double; emb_10: double; emb_11: double; emb_12: double; emb_13: double; emb_14: double; emb_15: double; column null counts=[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]. Declared feature checks: columns=18; dimensions=16.
What is a .parquet file?
Apache Parquet (.parquet) is a binary, columnar storage format for analytical data. It stores each column separately with per-column compression and encoding, embeds a schema and statistics, and is the de-facto standard for data lakes and engines like Spark, DuckDB, and pandas/pyarrow.
How to use this file
Use an example .parquet file to test columnar readers (pyarrow, DuckDB, Spark), schema and predicate-pushdown handling, and Parquet-to-CSV/JSON converters.
How to use this file for testing
“Text Embeddings: 16-dim (Parquet)” is a deterministic Testaroo fixture for ML training data, Embeddings, Data engineering, Conversion testing. Labelled, synthetic datasets in the shapes ML pipelines expect (JSONL for text tasks, image annotations, embeddings, and sample weights) for testing data loaders, tokenizers, and training tooling.
Documented properties for this file: seed 1729 · 24 rows · 18 columns. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
AI/ML fixtures are fully synthetic with documented schemas, no real people or data. Test data loaders, tokenizers, annotation converters, embedding/vector stores, or eval-metric parsers against the known structure and fixed seeds.
These are labelled, training-shaped fixtures with a documented schema. Test your data loader, tokenizer, or format converter against it; every label and value is synthetic.
Code examples
import pandas as pd  # pip install pyarrow

df = pd.read_parquet("embeddings.parquet")
print(df.head())
print(df.dtypes)
Generated by generation/ai_datasets.py. Free for any use, no attribution required, license.
Related files
- jsonDetection Annotations: COCO (JSON)Object-detection annotations for the scene in the COCO JSON format: images, categories, and per-object bounding boxes as [x, y, width, height]. Grouped with YOLO and Pascal-VOC twins for testing annotation-format conversion.
- xmlDetection Annotations: Pascal VOC (XML)The same detection boxes in the Pascal VOC XML format: a per-image annotation with size, and one object element per box with pixel corner coordinates. The XML twin of the COCO and YOLO annotations.
- xmlDetection Annotations: Warehouse Pascal VOC (XML)Pascal VOC XML annotations for the warehouse detection scene.
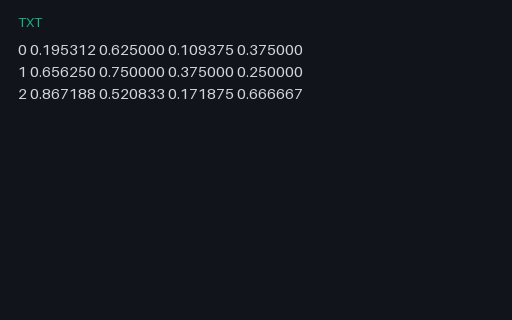
- txtDetection Annotations: YOLO (TXT)The same detection boxes in the YOLO text format: one object per line as class id and box centre, width, and height normalised to 0–1. The format twin of the COCO and VOC annotations.
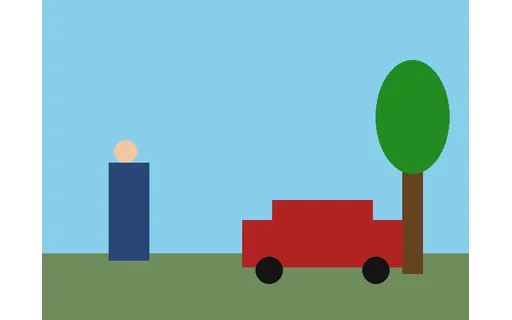
- pngObject-detection Scene (PNG, 640×480)A simple rendered street scene with a person, a car, and a tree at known pixel coordinates: the image the COCO, YOLO, and Pascal-VOC annotation twins describe. A fixture for testing object-detection loaders and annotation converters.
- safetensorsTiny Model Weights (safetensors)A genuinely-valid safetensors file with two small float32 tensors (36 parameters total): an 8×4 weight and a length-4 bias. The values are meaningless sample data, not a trained model; a fixture for testing safetensors loaders and weight inspectors.