Skip to content
Testaroo

Explore the test library

Find files, editable templates and browser test targets by what you need to make or test. The directory below is cut by format; the two collections under it cut the same library by subject and by workflow.

444 results

Page 15 of 19; 24 results per page.

Show the canonical directory
Preview of SRT: CJK (Japanese)
srt
246 B
Actual file preview for SRT: CJK (Japanese)

SRT: CJK (Japanese)

Japanese captions mixing kana, kanji and full-width punctuation. Full-width characters occupy two columns in a monospaced renderer, so line-length limits computed in code points under-count them.

File
SRT · Captions Encoding · 3 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: Cue Text Containing the Timestamp Arrow
srt
199 B
Actual file preview for SRT: Cue Text Containing the Timestamp Arrow

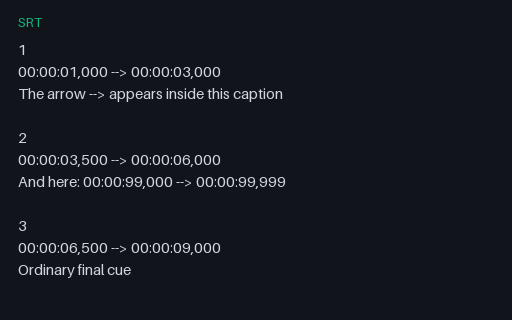
SRT: Cue Text Containing the Timestamp Arrow

Cue text that contains the --> separator, and a second cue whose text looks exactly like a timing line. A parser that finds timing lines by searching for '-->' anywhere rather than by tracking cue structure splits these into extra phantom cues. Structurally valid SubRip throughout: the file is correct and the naive parser is wrong.

File
SRT · Captions Edge · 3 cues
Use case
Subtitle parsingVideo QA· Conversion set
Preview of SRT: Cues Out of Chronological Order
srt
198 B
Actual file preview for SRT: Cues Out of Chronological Order

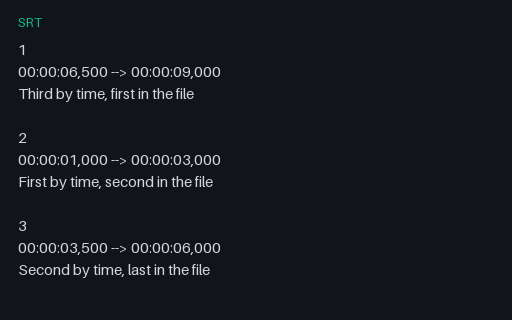
SRT: Cues Out of Chronological Order

Cue indices run 1, 2, 3 but the timestamps do not: the file is ordered 6.5s, 1.0s, 3.5s. The spec does not require chronological order, so a conforming parser must sort by start time rather than trusting file order. Parsers that stream cues straight to a renderer show them in the wrong sequence.

File
SRT · Captions Edge · 3 cues
Use case
Subtitle parsingVideo QA· Conversion set
Preview of SRT: Cyrillic
srt
208 B
Actual file preview for SRT: Cyrillic

SRT: Cyrillic

Cyrillic captions: outside ASCII but still single-width and left-to-right, which isolates encoding handling from layout handling.

File
SRT · Captions Encoding · 2 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: Emoji and combining marks
srt
247 B
Actual file preview for SRT: Emoji and combining marks

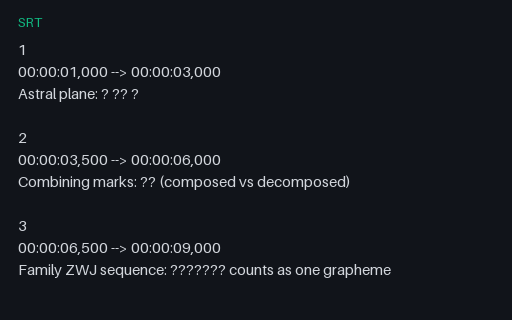
SRT: Emoji and combining marks

Characters above the Basic Multilingual Plane, a composed/decomposed accent pair, and a zero-width-joiner sequence. Anything that measures caption length in UTF-16 code units rather than graphemes miscounts these.

File
SRT · Captions Encoding · 3 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: HTML Entities and Angle Brackets in Cue Text
srt
296 B
Actual file preview for SRT: HTML Entities and Angle Brackets in Cue Text

SRT: HTML Entities and Angle Brackets in Cue Text

Cue text mixing escaped entities, raw ampersands, unescaped angle brackets used as maths, and one genuine italic tag. SubRip has no formal escaping rules, so every parser draws the line somewhere different. Shows immediately whether a tool decodes entities, passes them through, or mistakes '3 < 5' for an unclosed tag and swallows the rest of the line.

File
SRT · Captions Edge · 4 cues
Use case
Subtitle parsingVideo QA· Conversion set
Preview of SRT: Mixed CRLF and LF Line Endings
srt
359 B
Actual file preview for SRT: Mixed CRLF and LF Line Endings

SRT: Mixed CRLF and LF Line Endings

One file with both line-ending conventions: CRLF for the opening cues and bare LF for the rest, the shape a caption file takes after being edited on two platforms or assembled from two sources. Parsers that detect the convention once from the first line and then apply it to the whole file mis-split everything after the switch.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: No Trailing Newline
srt
351 B
Actual file preview for SRT: No Trailing Newline

SRT: No Trailing Newline

Identical to the reference file except the final newline is missing, so the last cue is terminated by end-of-file rather than by a blank line. SubRip separates cues with a blank line, and parsers that split on a double newline and discard the remainder drop the final cue entirely: a bug that is invisible until a file happens to end this way.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: Over-Long Caption Line
srt
405 B
Actual file preview for SRT: Over-Long Caption Line

SRT: Over-Long Caption Line

One caption line of 334 characters against a 32-column broadcast convention. Exercises wrapping, truncation and validation paths, and shows immediately whether a burn-in tool wraps text or lets it run off the frame.

File
SRT · Captions Edge · 2 cues
Use case
Subtitle parsingVideo QA· Conversion set
Preview of SRT: Overlapping Cues
srt
182 B
Actual file preview for SRT: Overlapping Cues

SRT: Overlapping Cues

Three cues whose time ranges deliberately overlap, so at 3.2 seconds all three are active at once. Legal in SubRip and common in multi-speaker transcripts, but plenty of renderers assume one cue at a time and either drop the extras or stack them off-screen.

File
SRT · Captions Edge · 3 cues
Use case
Subtitle parsingVideo QA· Conversion set
Preview of SRT: RTL (Arabic)
srt
244 B
Actual file preview for SRT: RTL (Arabic)

SRT: RTL (Arabic)

Right-to-left Arabic with joined letterforms, including a bidirectional line where Western digits sit inside RTL text. Exercises the bidi algorithm and any renderer that assumes left-to-right layout.

File
SRT · Captions Encoding · 3 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: RTL (Hebrew)
srt
159 B
Actual file preview for SRT: RTL (Hebrew)

SRT: RTL (Hebrew)

Right-to-left Hebrew without letter joining: a second RTL script, so a renderer cannot pass by special-casing Arabic shaping alone.

File
SRT · Captions Encoding · 2 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: Speaker Labels and Dialogue Dashes
srt
335 B
Actual file preview for SRT: Speaker Labels and Dialogue Dashes

SRT: Speaker Labels and Dialogue Dashes

The conventions captioners actually use: speaker names in caps, leading dashes for alternating dialogue, square brackets and parentheses for sound effects, and music notes around lyrics. None is part of the SubRip grammar, so tools that extract speaker names or strip non-speech cues have to pattern-match them. Useful for testing transcript extraction and caption-cleaning passes.

File
SRT · Captions Edge · 5 cues
Use case
Subtitle parsingVideo QA· Conversion set
Preview of SRT: UTF-16 BE with BOM
srt
686 B
Actual file preview for SRT: UTF-16 BE with BOM

SRT: UTF-16 BE with BOM

UTF-16 big-endian with a BOM: the byte order most decoders forget to handle, since little-endian dominates in practice. Identical cue content across the whole set, so any difference in a parser's output is an encoding bug and nothing else.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: UTF-16 LE with BOM
srt
686 B
Actual file preview for SRT: UTF-16 LE with BOM

SRT: UTF-16 LE with BOM

UTF-16 little-endian with a BOM. Every second byte is NUL, so a parser that reads bytes as UTF-8 or ASCII sees a file that appears to start and end immediately. Tools must detect the BOM, not assume UTF-8. Identical cue content across the whole set, so any difference in a parser's output is an encoding bug and nothing else.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: UTF-8 with BOM, CRLF
srt
375 B
Actual file preview for SRT: UTF-8 with BOM, CRLF

SRT: UTF-8 with BOM, CRLF

Both awkward properties at once (a BOM and CRLF endings), which is what a file saved by Notepad on Windows actually looks like. Identical cue content across the whole set, so any difference in a parser's output is an encoding bug and nothing else.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: UTF-8 with BOM, LF
srt
355 B
Actual file preview for SRT: UTF-8 with BOM, LF

SRT: UTF-8 with BOM, LF

UTF-8 with a leading U+FEFF byte-order mark. Windows caption tools emit this constantly, and a parser that does not strip it sees the BOM as part of the first cue number and fails to match its index. Identical cue content across the whole set, so any difference in a parser's output is an encoding bug and nothing else.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: UTF-8, CRLF
srt
372 B
Actual file preview for SRT: UTF-8, CRLF

SRT: UTF-8, CRLF

UTF-8 with Windows CRLF line endings. Parsers that split on a bare \n leave a trailing carriage return on every line, which usually surfaces as a stray box glyph at the end of each caption. Identical cue content across the whole set, so any difference in a parser's output is an encoding bug and nothing else.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set
Preview of SRT: UTF-8, LF
srt
352 B
Actual file preview for SRT: UTF-8, LF

SRT: UTF-8, LF

Plain UTF-8, no byte-order mark, Unix LF line endings. The reference member of this set: every other file here carries the same five cues, so a parser's output can be diffed against this one. Identical cue content across the whole set, so any difference in a parser's output is an encoding bug and nothing else.

File
SRT · Captions Encoding · 5 cues
Use case
Caption encodingSubtitle parsing+1· Conversion set