Protobuf: Encoded Message
A single protobuf User message in binary wire format (varint + length-delimited fields): the serialized counterpart to the user.proto schema. For testing protobuf decoders without the generated code.
| fieldwire | value |
|---|---|
| id (1, varint) | 1001 |
| name (2, len) | Ada Lovelace |
| email (3, len) | ada.lovelace@example.com |
| role (4, varint) | ROLE_MEMBER (2) |
Specifications
- Rows
- 5
- Columns
- 7
- Format
- Protocol Buffers (wire format)
- Message
- User
- Note
- matches schema.graphql's sibling user.proto
Testing contract
Expected to pass- Scenario
- Exercise Protobuf: Encoded Message in its binary workflow. A single protobuf User message in binary wire format (varint + length-delimited fields): the serialized counterpart to the user.proto schema.
- Expected result
- field 1, wire 0: varint 1001; field 2, wire 2: 12 payload bytes; field 3, wire 2: 24 payload bytes; field 4, wire 0: varint 2. Declared feature checks: columns=7; message=User.
What is a .pb file?
A .pb file holds Protocol Buffers binary data: Google's compact, schema-driven serialization where field numbers and wire types encode the message. Without the matching .proto schema the bytes are opaque, which makes it efficient but not self-describing.
How to use this file
Use an example .pb file to test protobuf decoders (with the matching schema), wire-format parsing, and protobuf tooling.
How to use this file for testing
“Protobuf: Encoded Message” is a deterministic Testaroo fixture for Conversion testing, Serialization testing. The same content exported across many formats and linked as a group, so you can convert one and diff against the expected twin.
Documented properties for this file: 5 rows · 7 columns · Protocol Buffers (wire format). Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Generated by generation/data_binary.py. Free for any use, no attribution required, license.
Related files
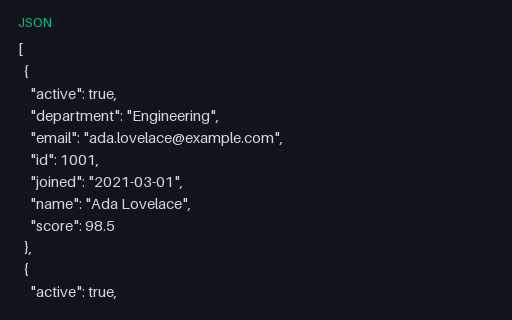
- bsonBSON: Binary JSON (MongoDB)The records as BSON: the binary-JSON encoding MongoDB stores documents in. For testing BSON decoders and JSON↔BSON conversion.
- cborCBOR: Concise Binary ObjectThe records as CBOR: the IETF concise binary object representation used in IoT and COSE/WebAuthn. For testing CBOR decoders and JSON↔CBOR conversion.
- msgpackMessagePack: Binary JSONThe records as MessagePack: a compact binary serialization that maps onto the JSON data model, common in caches and RPC. For testing MessagePack codecs and JSON↔MessagePack conversion.
- orcConvert v2 ORC Employee Table SourceBinary orc source for the five-row P8 employee conversion table, preserving ids, names, departments, booleans, and scores. Stable P8 artifact p8-convert-orc-source.
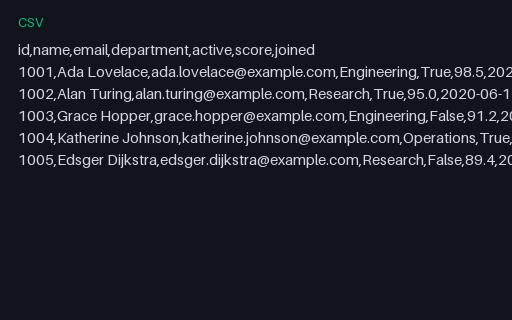
- csvConvert v2 ORC Expected CSVCsv semantic reference for the five-row P8 employee conversion table, preserving ids, names, departments, booleans, and scores. Stable P8 artifact p8-convert-orc-csv.
- jsonConvert v2 ORC Expected JSONJson semantic reference for the five-row P8 employee conversion table, preserving ids, names, departments, booleans, and scores. Stable P8 artifact p8-convert-orc-json.