CSV: UTF-8 with BOM
A CSV prefixed with a UTF-8 BOM (EF BB BF) and accented / CJK cells, for testing BOM-aware importers.
id,name,city,note
1,Ada,Lisbon,café
2,José,München,naïve
3,陈,東京,サンプル
Specifications
- Encoding
- UTF-8 with BOM
- Rows
- 3
- Has BOM
- true
Testing contract
Expected to pass- Scenario
- Exercise CSV: UTF-8 with BOM in its encodings workflow. A CSV prefixed with a UTF-8 BOM (EF BB BF) and accented / CJK cells, for testing BOM-aware importers.
- Expected result
- 3 data records using ',' delimiters and utf-8-sig; header fields are id, name, city, note; data-record widths (columns:count) are {"4":3}. Declared feature checks: hasBOM=True.
What is a .csv file?
CSV (Comma-Separated Values) is a plain-text tabular format where rows are lines and fields are separated by commas, with quoting rules for values that contain delimiters, quotes, or newlines. It has no formal type system and depends on encoding and dialect conventions. It is the most portable format for tabular data exchange.
How to use this file
Use an example CSV to test parsers against quoting and embedded-delimiter edge cases, header handling, encoding detection, and import pipelines into databases or spreadsheets.
How to use this file for testing
“CSV: UTF-8 with BOM” is a deterministic Testaroo fixture for CSV parsing, Encoding detection, Data import. Clean and deliberately messy CSVs, quoted commas, embedded newlines, ragged rows, odd delimiters, and encodings.
Documented properties for this file: 3 rows · UTF-8 with BOM. Compare results against paired or grouped companions on this page when present (clean↔damaged, searchable↔scanned, or format twins) so scores stay reproducible across runs.
Download the file once, keep the path stable in CI or local scripts, and treat the spec table as the contract: dimensions, seeds, field lists, and roles are intentional. Corrupt or invalid samples are labelled as such, expect parsers to fail loudly rather than silently accept them.
Data fixtures document their exact quirks (delimiters, encodings, null handling, schema, and row counts) in the spec table. Point your parser or importer at the file and assert it handles the documented edge cases; clean and deliberately-messy siblings make before/after diffs straightforward.
Feed the file to your parser and assert it handles the documented quirks, quoted delimiters, embedded newlines, ragged rows, or invalid syntax; the valid↔invalid distinction is labelled in the title.
Code examples
import pandas as pd

df = pd.read_csv("utf8-bom.csv")
print(df.head())
print(df.dtypes)
Generated by generation/data_encodings_wave_c.py. Free for any use, no attribution required, license.
Related files
- txtFixed-Width Positions File (TXT)A classic fixed-width text extract with documented column positions, for COBOL-style / mainframe importer tests.
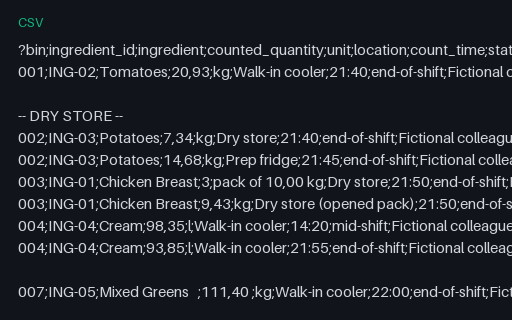
- csvAlder Table Bistro: Inventory count sheet as transcribedInventory count sheet as transcribed for Alder Table Bistro. The same closing counts as inventory-count-sheet.csv, in the shape a paper count actually arrives in. CRLF line endings, a UTF-8 byte order mark, a semicolon delimiter and a decimal comma. Two blank lines, one section banner that is not a record, one ingredient split across two locations, one counted as whole packs plus a remainder, one superseded mid-shift row at 14:20, trailing whitespace in three fields, a leading-zero bin code, an empty bin code, and one record carrying ten fields where the header declares 9. Every quirk is named in README.md.
- csvAlder Table Bistro: Supplier price list CSV, semicolon and decimal commaSupplier price list CSV, semicolon and decimal comma for Alder Table Bistro. The same 48 price rows re-exported the way a European supplier portal writes them: UTF-8 with a byte-order mark (EF BB BF), semicolon field separators, CRLF line endings, and decimal commas in list_unit_price, price_per_case and contract_tier_unit_price. Column names, column order and every value are identical to price-list.csv; only the encoding and the separators differ.
- csvAlder Table Bistro: Till import in the European dialectTill import in the European dialect for Alder Table Bistro. The same 21 rows as pos-import.csv in the other dialect a till exports: semicolon delimited, decimal comma in the price column, Latin-1 encoded and CRLF terminated. It carries the non-ASCII characters "é", so reading it as UTF-8 raises a decode error instead of silently producing mojibake.
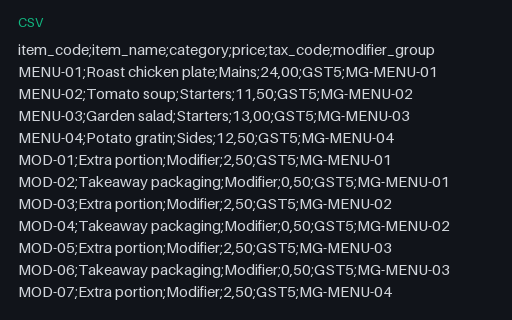
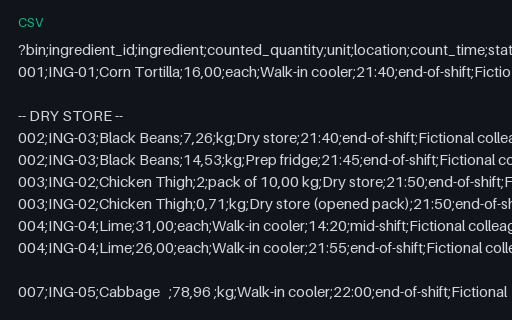
- csvCedar Street Tacos: Inventory count sheet as transcribedInventory count sheet as transcribed for Cedar Street Tacos. The same closing counts as inventory-count-sheet.csv, in the shape a paper count actually arrives in. CRLF line endings, a UTF-8 byte order mark, a semicolon delimiter and a decimal comma. Two blank lines, one section banner that is not a record, one ingredient split across two locations, one counted as whole packs plus a remainder, one superseded mid-shift row at 14:20, trailing whitespace in three fields, a leading-zero bin code, an empty bin code, and one record carrying ten fields where the header declares 9. Every quirk is named in README.md.
- csvCedar Street Tacos: Supplier price list CSV, semicolon and decimal commaSupplier price list CSV, semicolon and decimal comma for Cedar Street Tacos. The same 48 price rows re-exported the way a European supplier portal writes them: UTF-8 with a byte-order mark (EF BB BF), semicolon field separators, CRLF line endings, and decimal commas in list_unit_price, price_per_case and contract_tier_unit_price. Column names, column order and every value are identical to price-list.csv; only the encoding and the separators differ.