jsonl
569 BImage Caption Dataset (JSONL)
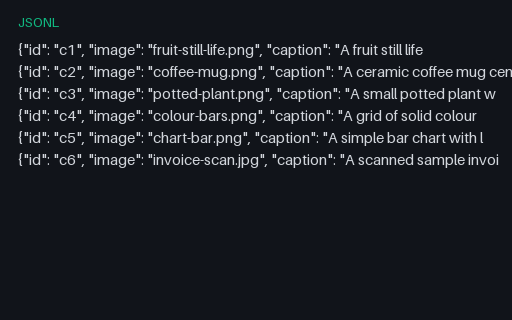
Six synthetic image-caption pairs in JSON Lines, for testing captioning loaders and vision-language eval harnesses.
- File
- JSONL · Vision · 6 records
- Use case
- Computer visionML training data+1
Find files, editable templates and browser test targets by what you need to make or test. The directory below is cut by format; the two collections under it cut the same library by subject and by workflow.
Page 3 of 6; 24 results per page.
Six synthetic image-caption pairs in JSON Lines, for testing captioning loaders and vision-language eval harnesses.
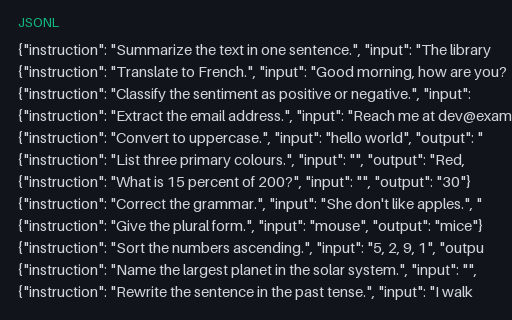
An instruction-tuning dataset in the Alpaca JSONL format: 20 instruction / input / output triples covering small transformations, extraction, and factual answers. Fully synthetic; a fixture for supervised fine-tuning pipelines.
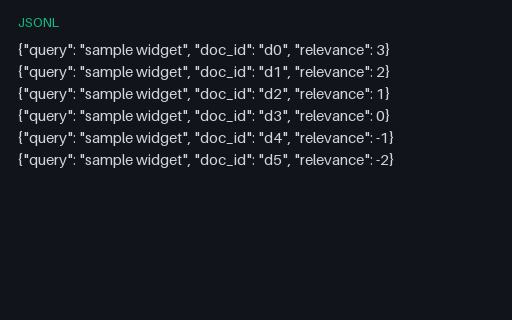
Query-document relevance grades for learning-to-rank training and eval.
Listwise ranked doc lists for nDCG and listwise loss tests.
A short Markdown document in the mini RAG corpus (doc-a.md). Retrieve against the paired queries JSON.
A short Markdown document in the mini RAG corpus (doc-b.md). Retrieve against the paired queries JSON.
A short Markdown document in the mini RAG corpus (doc-c.md). Retrieve against the paired queries JSON.
A short Markdown document in the mini RAG corpus (doc-d.md). Retrieve against the paired queries JSON.
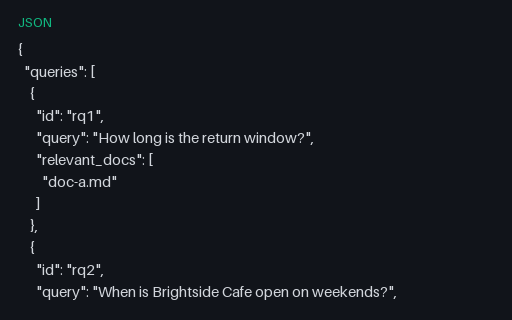
Retrieval-eval queries with relevant_docs pointers into the mini RAG Markdown corpus.
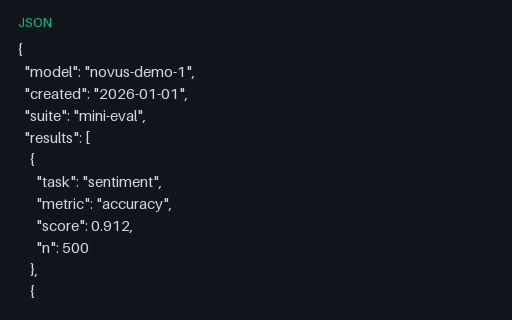
A model-evaluation summary in JSON, per-task scores for a fictional model across sentiment, NER, summarization, translation, and QA, each with its metric and sample size. A fixture for testing eval dashboards and leaderboard importers.
Mean reciprocal rank ground truth for search eval harness tests.
Multi-step agent action/observation trace for ReAct-style eval harnesses.
DE image captions referencing Wave F detection scenes.
EN image captions referencing Wave F detection scenes.
ES image captions referencing Wave F detection scenes.
FR image captions referencing Wave F detection scenes.
JA image captions referencing Wave F detection scenes.
Parallel EN/ES/FR/DE captions per image for multilingual eval.
EN/ES sentence embeddings for cross-lingual similarity tests.
A token-classification dataset in JSON Lines: 16 tokenized sentences with aligned BIO tags for person, organisation, and location entities. All names, companies, and places are fictional. A fixture for NER model training and sequence-labelling tooling.
Precomputed DCG/nDCG values for ranking metric unit tests.
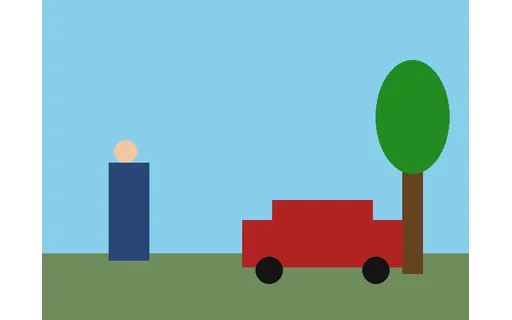
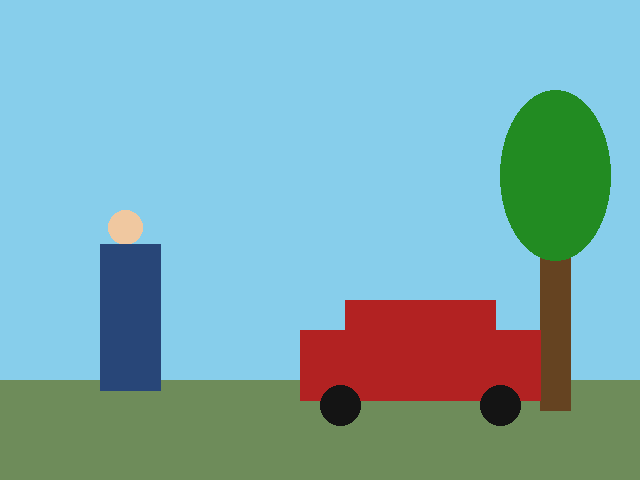
A simple rendered street scene with a person, a car, and a tree at known pixel coordinates: the image the COCO, YOLO, and Pascal-VOC annotation twins describe. A fixture for testing object-detection loaders and annotation converters.
A single multi-turn chat example for an OCR assistant: system/user/assistant roles in JSONL.
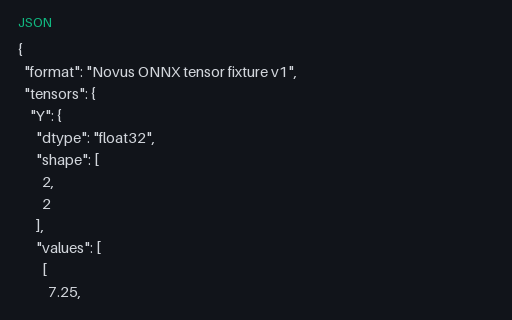
The reference-evaluator output for the Affine MatMul plus Add model and supplied input, including shape, dtype, exact values and a 1e-6 tolerance.