json
156 BQuantized int8 Embeddings (JSON)
int8-quantised embedding vector for quantised vector search tests.
- File
- JSON · Embeddings
- Use case
- ML training data
Find files, editable templates and browser test targets by what you need to make or test. The directory below is cut by format; the two collections under it cut the same library by subject and by workflow.
Page 5 of 6; 24 results per page.
int8-quantised embedding vector for quantised vector search tests.
Short query list for ranking benchmark harness smoke tests.
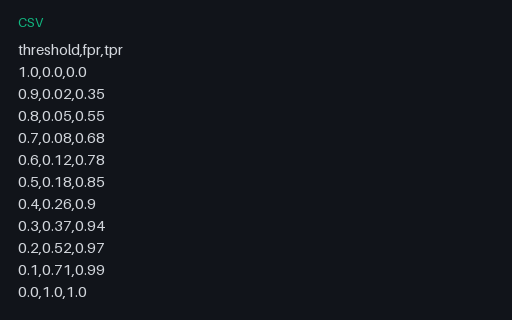
An ROC curve as CSV: decision threshold with the corresponding false-positive and true-positive rates, monotonic from (0,0) to (1,1). A fixture for testing chart tools and AUC calculators.
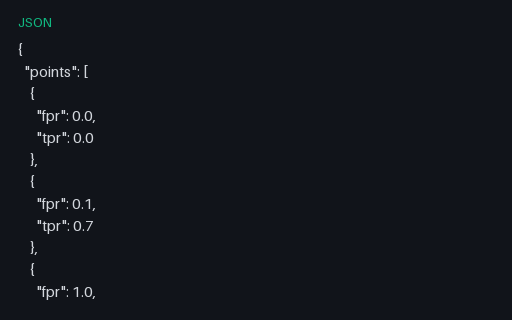
ROC curve coordinate list for AUC calculator tests.
Named-entity spans over fictional SAMPLE PII sentences, for redaction/NER tooling tests.
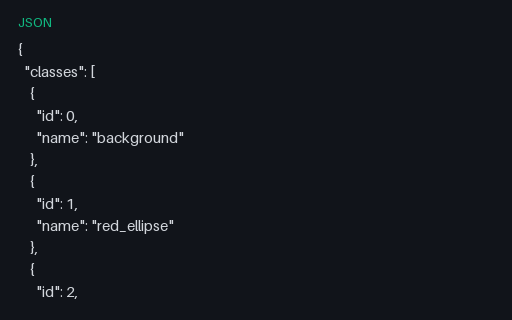
Class-id to name map for the semantic-segmentation mask (background + three shapes).
Indexed 8-bit mask (0=background, 1–3=shapes) for the semantic-segmentation scene twin.
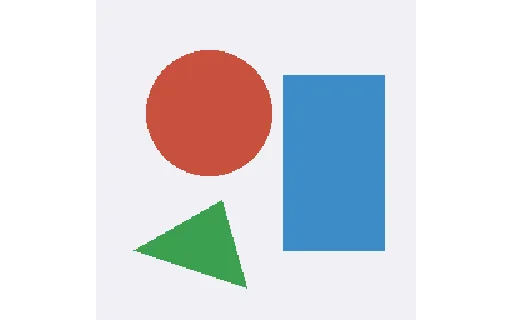
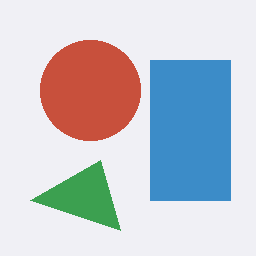
A synthetic RGB scene with three coloured shapes: input for semantic-segmentation models. Pair with the indexed mask twin.
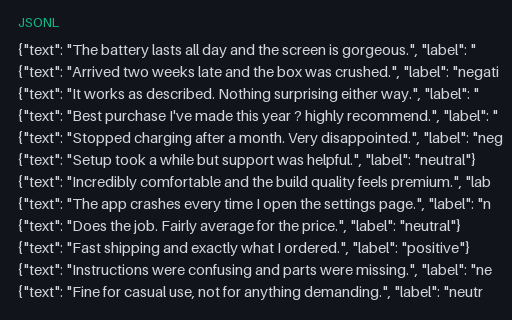
A labelled sentiment-classification dataset in JSON Lines: 24 short product-review-style sentences balanced across positive, negative, and neutral. Fully synthetic; a fixture for testing text-classification loaders, tokenizers, and JSONL parsers.
sklearn-style classification report text for parser snapshot tests.
An abstractive-summarization dataset in JSON Lines: 15 short synthetic news-style documents each paired with a one-sentence summary. A fixture for training and evaluating summarization models and for testing JSONL ingestion.
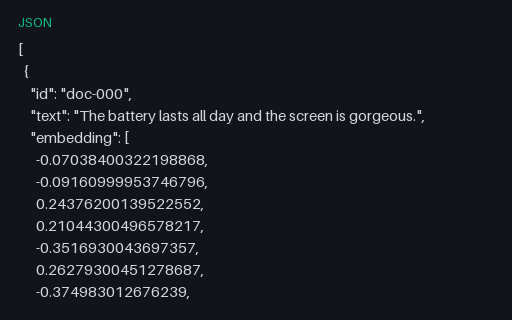
A set of 24 L2-normalised 16-dimensional text embeddings as JSON: each record pairs an id and its source text with a float vector. A fixture for testing vector stores, similarity search, and embedding loaders. Parquet and .npy twins included.
The same 16-dimensional embeddings as Apache Parquet: id and text columns plus one column per dimension. The columnar twin, for testing analytics engines and Parquet-based vector pipelines.
The embeddings as a raw NumPy array: a 24×16 float32 matrix in .npy format, loadable with numpy.load. The binary twin of the JSON and Parquet files, for testing tensor and matrix loaders.
L2-normalised 8-dimensional text embeddings in JSON, for vector store loader tests.
NumPy matrix twin of the Wave F 8-dim embeddings.
A genuinely-valid safetensors file with two small float32 tensors (36 parameters total): an 8×4 weight and a length-4 bias. The values are meaningless sample data, not a trained model; a fixture for testing safetensors loaders and weight inspectors.
Function-call result rows decoupled from chat messages for router testing.
SAMPLE tool-calling JSON (tool-call-search) for agent harness schema tests.
SAMPLE tool-calling JSON (tool-call-weather) for agent harness schema tests.
SAMPLE tool-calling JSON (tool-error-unknown) for agent harness schema tests.
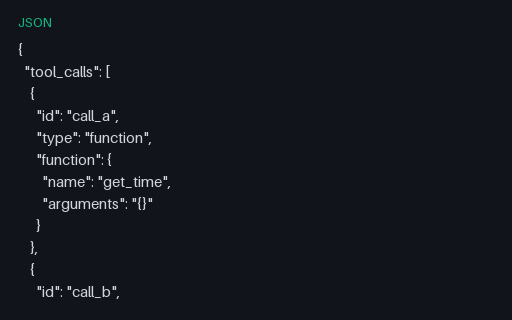
SAMPLE tool-calling JSON (tool-parallel-two) for agent harness schema tests.
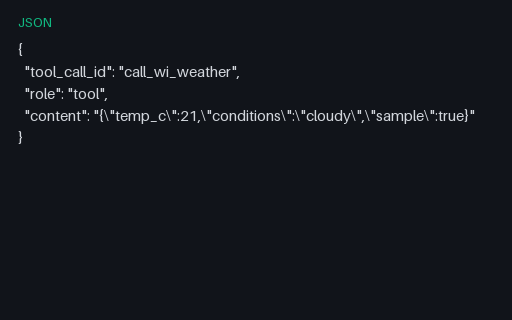
SAMPLE tool-calling JSON (tool-result-weather) for agent harness schema tests.